Latest issue
The Error Budget Was Supposed to End the Argument. It Just Relocated It.
10/25/2026
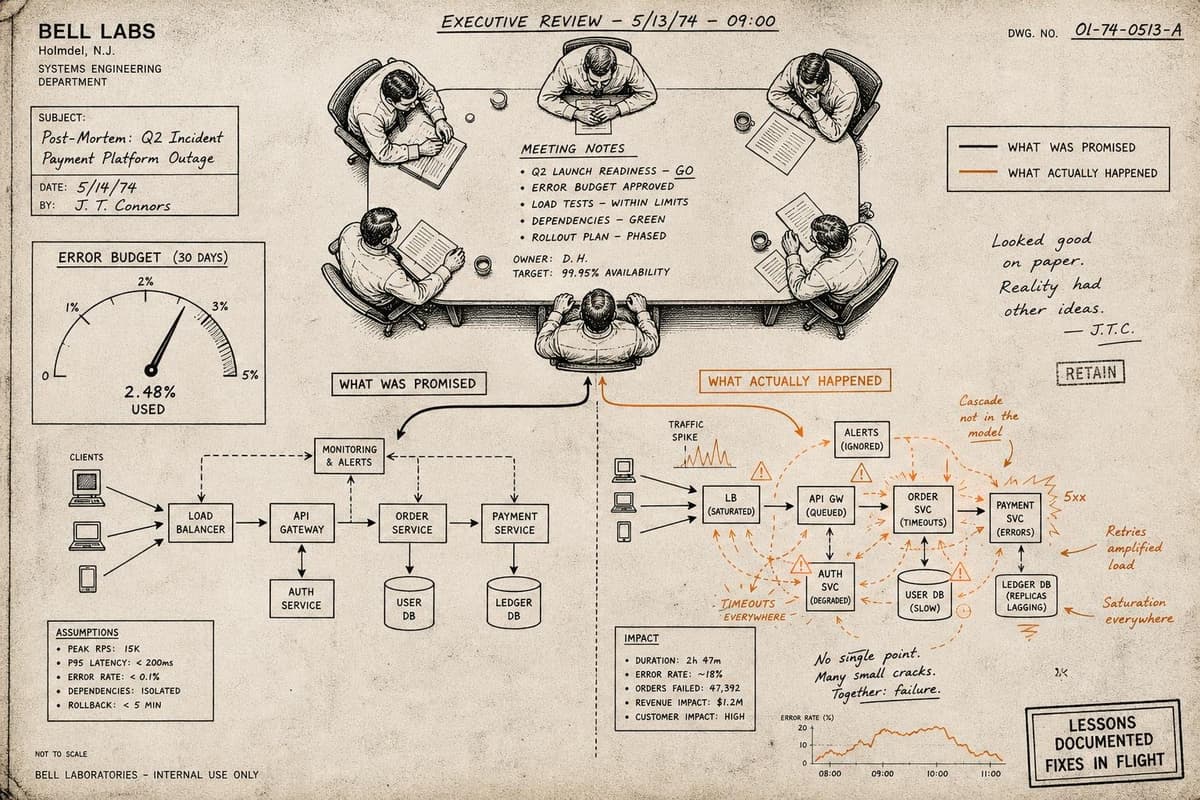
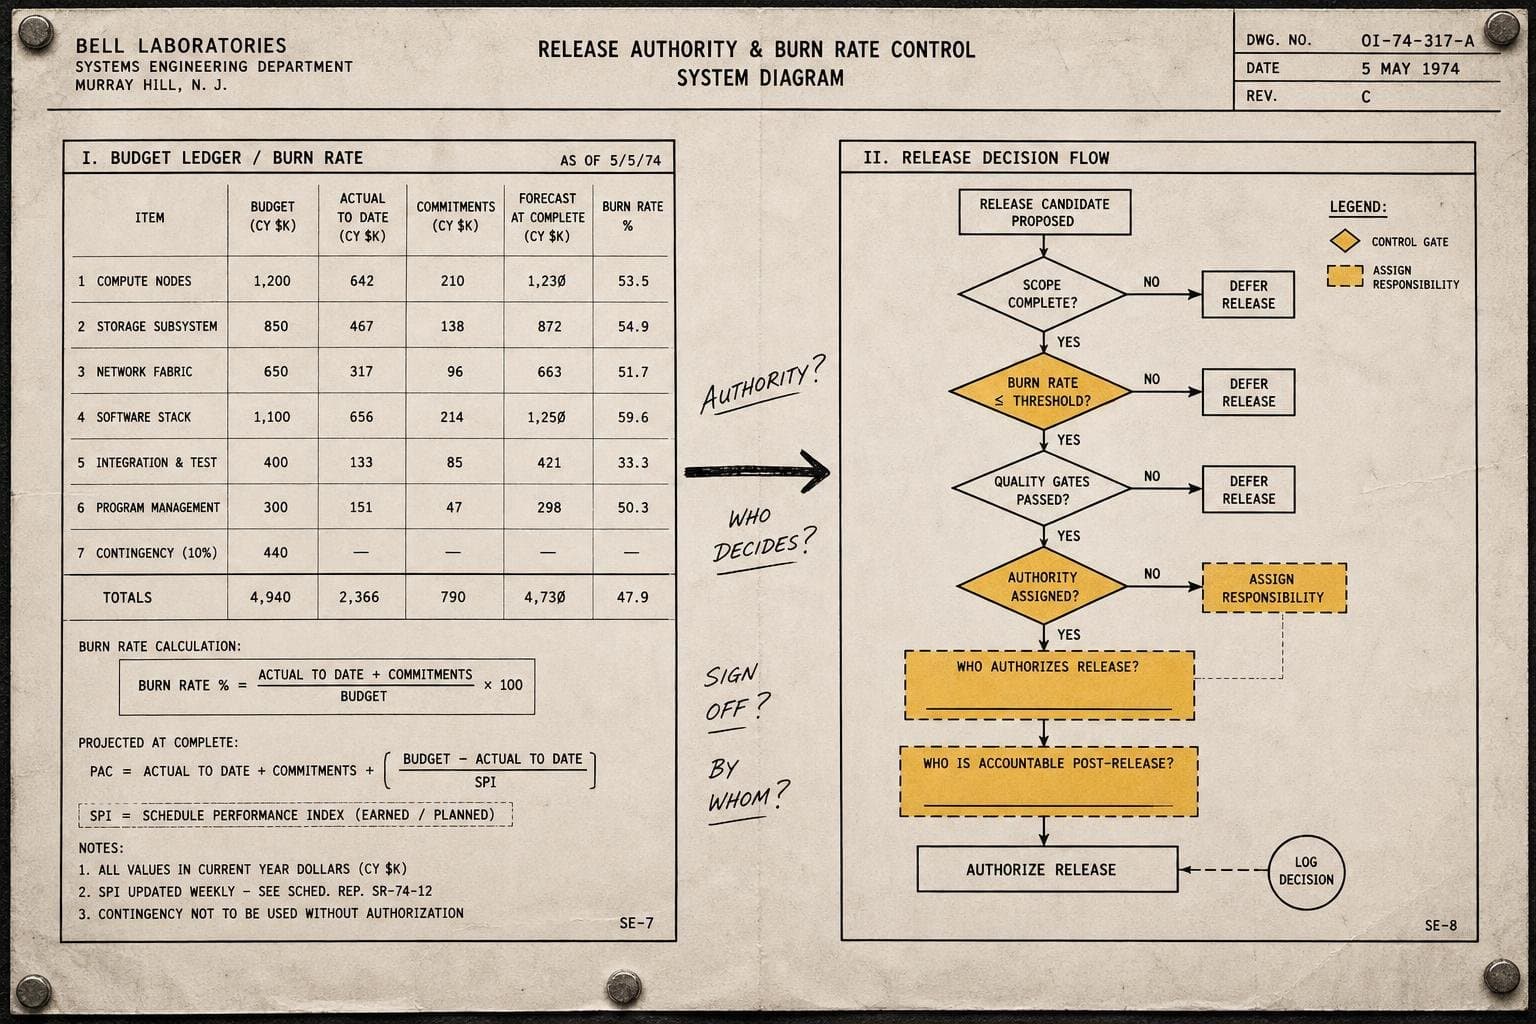
Somewhere there's a VP who thinks the error budget solved the fight between product and reliability. The budget was supposed to be the thing that made the tradeoff explicit — burn it, and you slow down; stay under it, and you ship. Clean. Quantitative. No more Friday-afternoon sh…
Recent posts
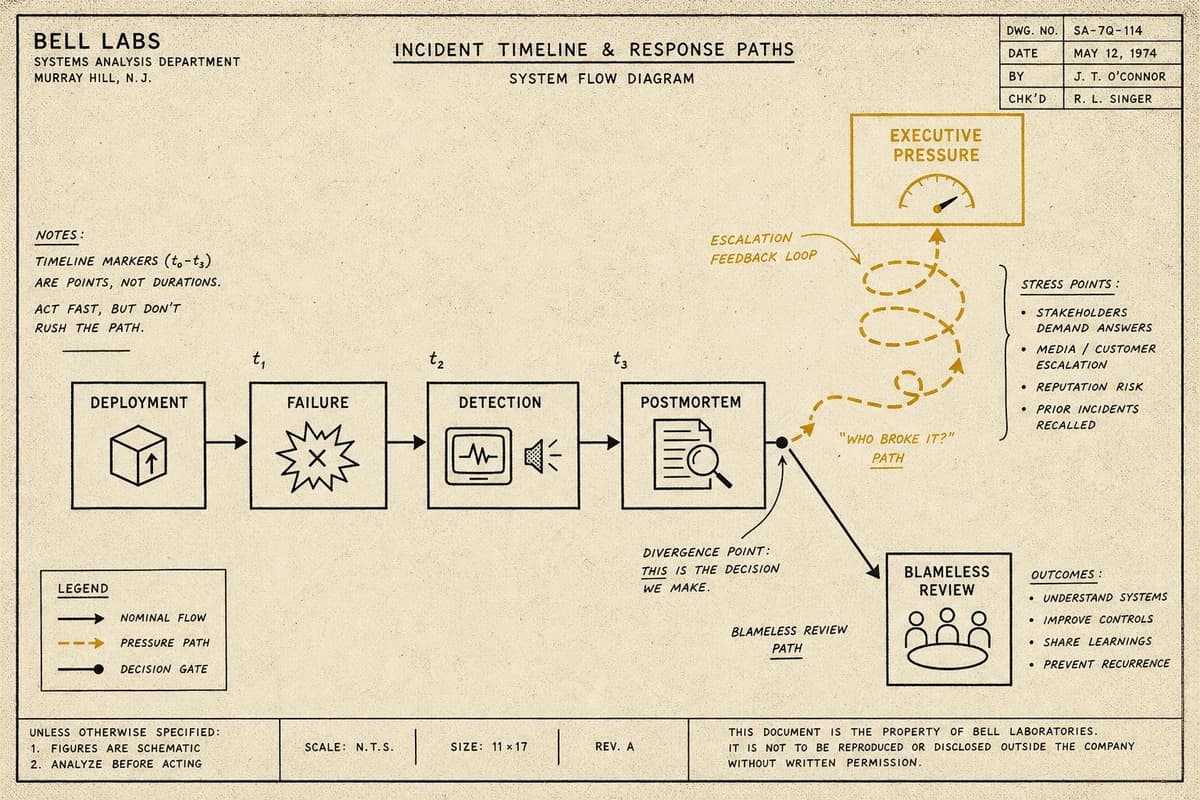
Every team says their postmortems are blameless. Almost none of them are, not really, not when it counts. The policy holds fine for the garden-variety outage — a bad config push, a…
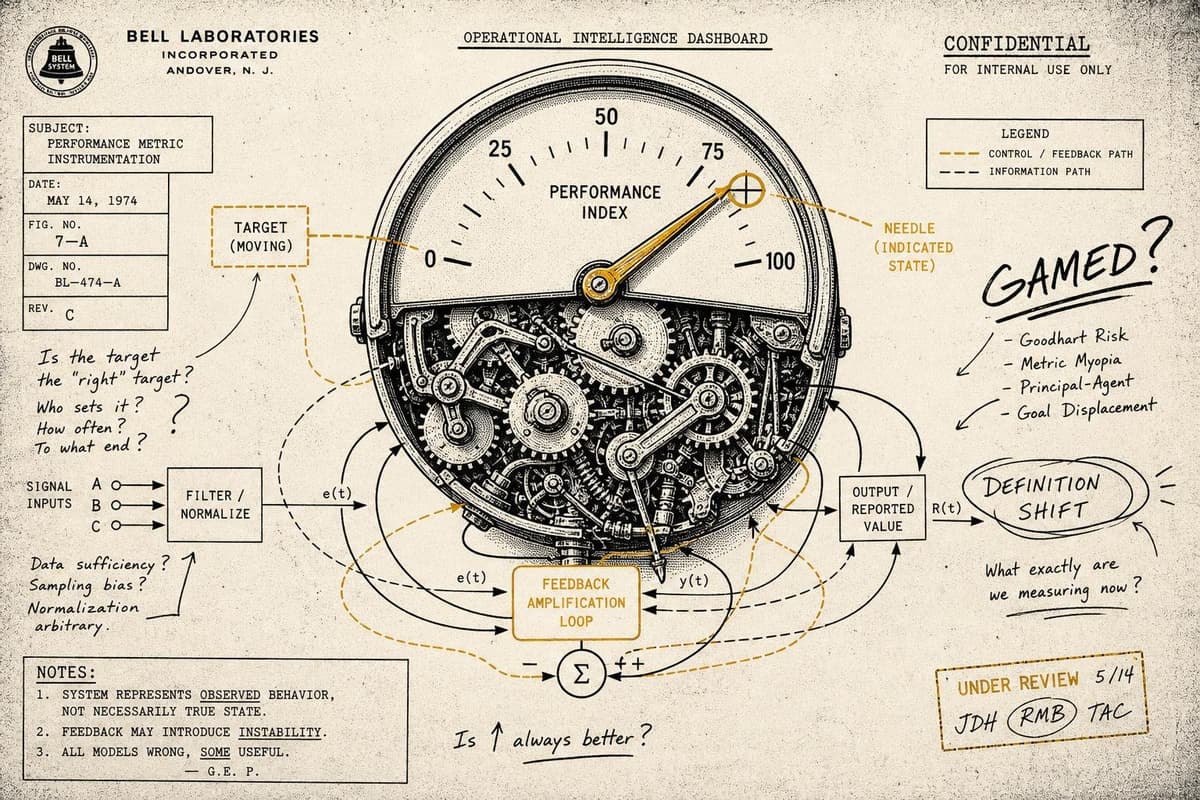
Every team I've watched chase a reliability number eventually starts managing the number instead of the system. It's not malice. It's incentive gravity. Once a dashboard decides wh…
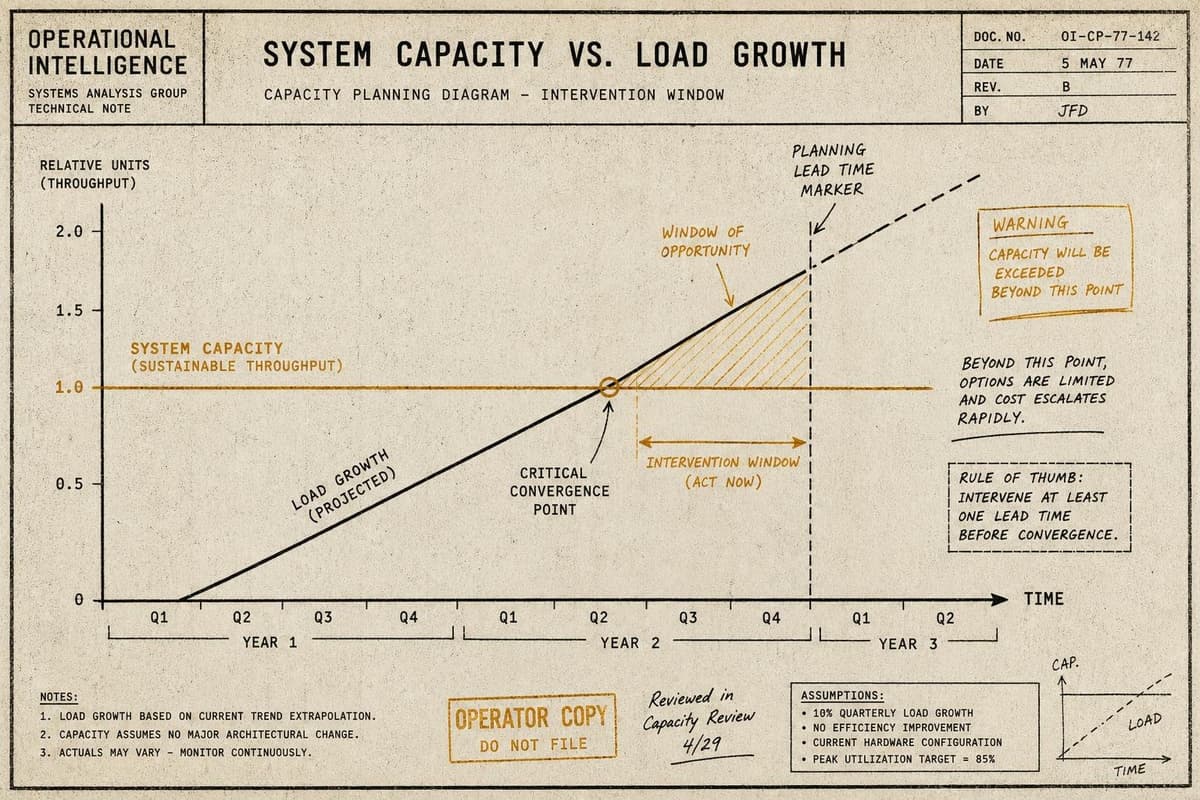
Nobody gets paged because capacity planning didn't happen. That's the problem. The pager goes off because a queue backed up, a database ran out of connections, or a service started…
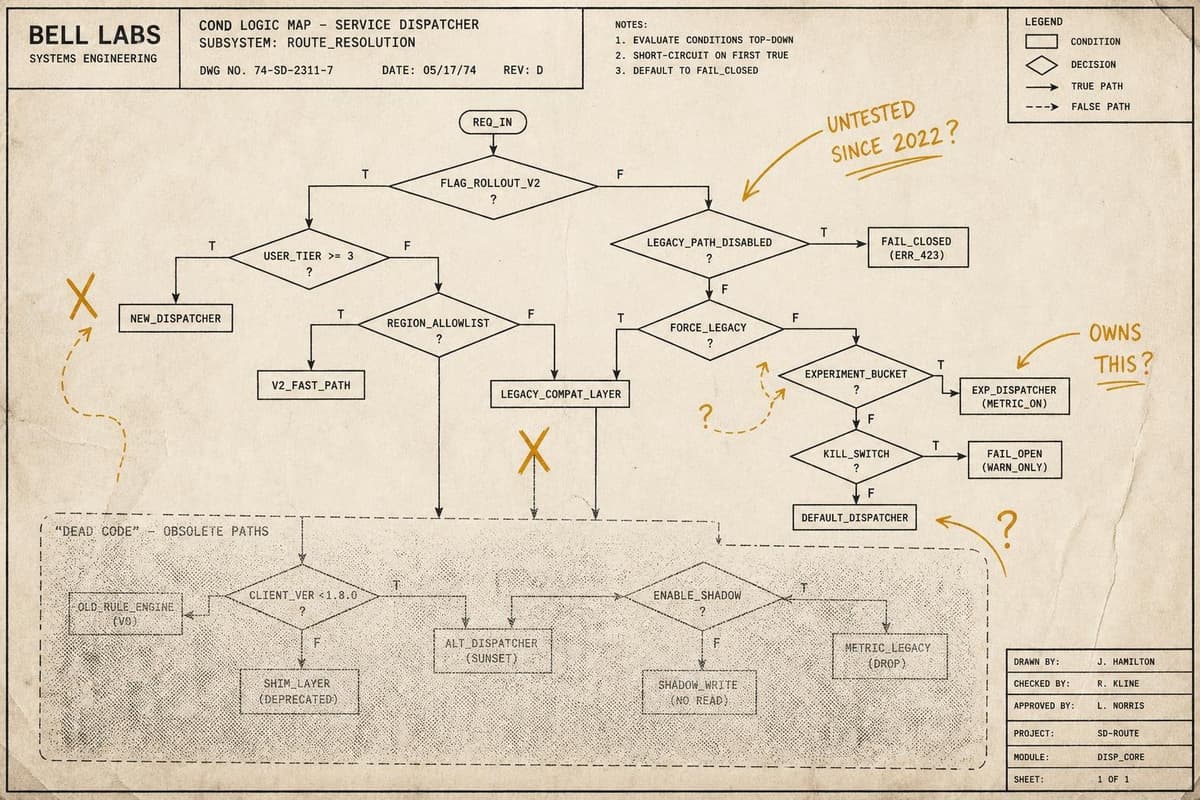
Every team that adopts feature flags does it for the same reason: to decouple deploy from release, and to have a fast, low-risk way to turn something off when it goes sideways. Tha…
There's a specific kind of dread that hits when you're mid-incident and you realize the one person who actually understands this service is on a plane to Lisbon. Not because the do…
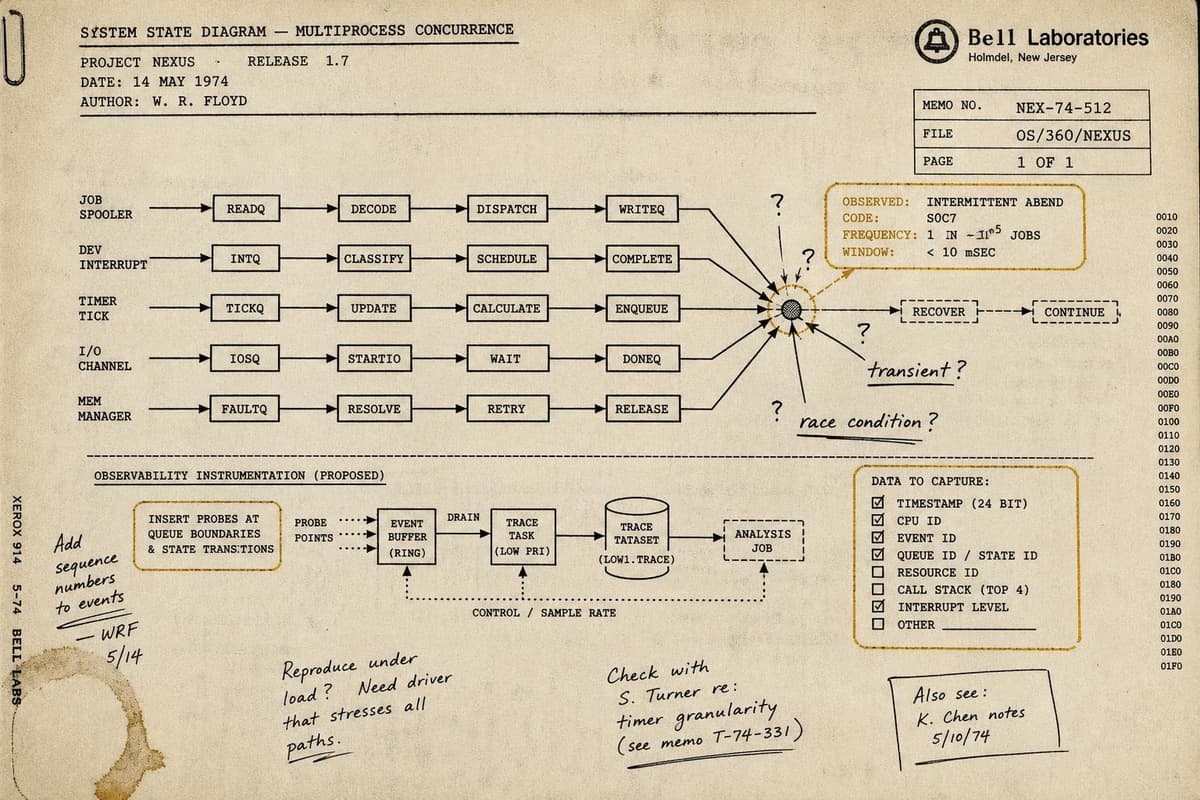
The most dangerous postmortem is the one where the team leaves the room saying "we still don't know why it happened." Not because the unknown is inherently dangerous — production s…
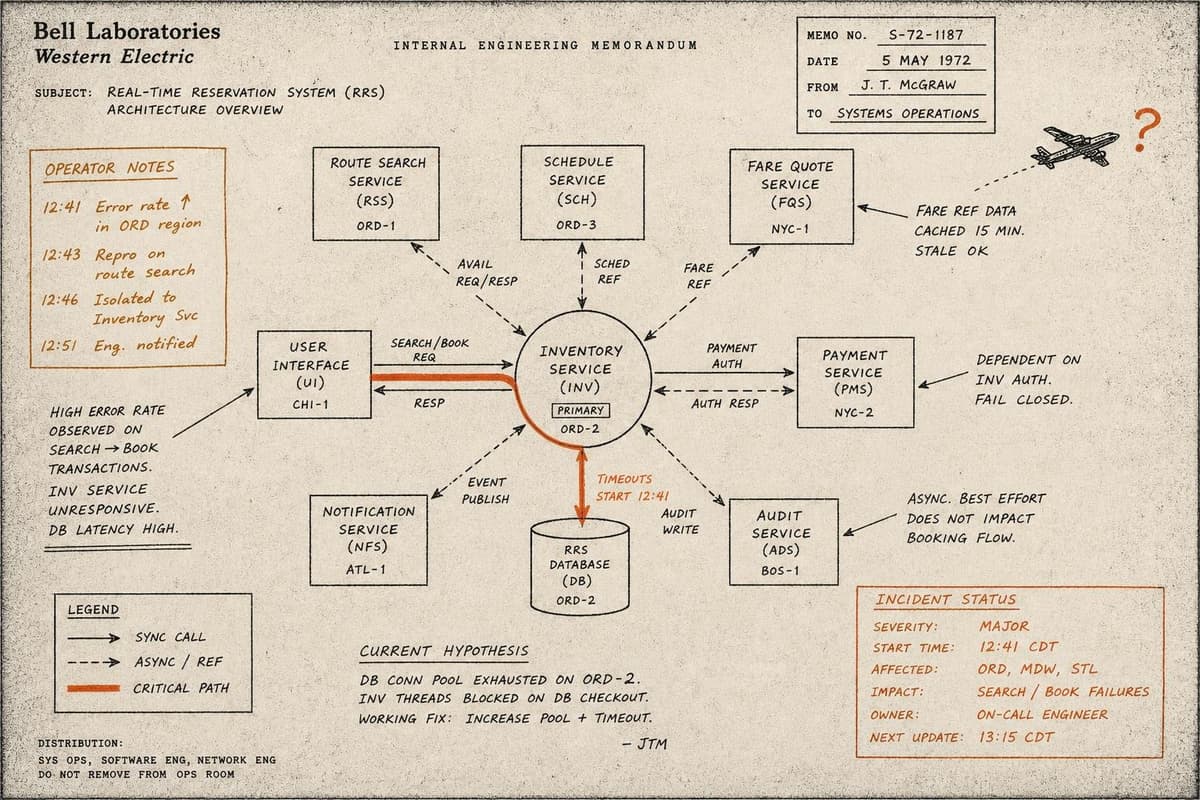
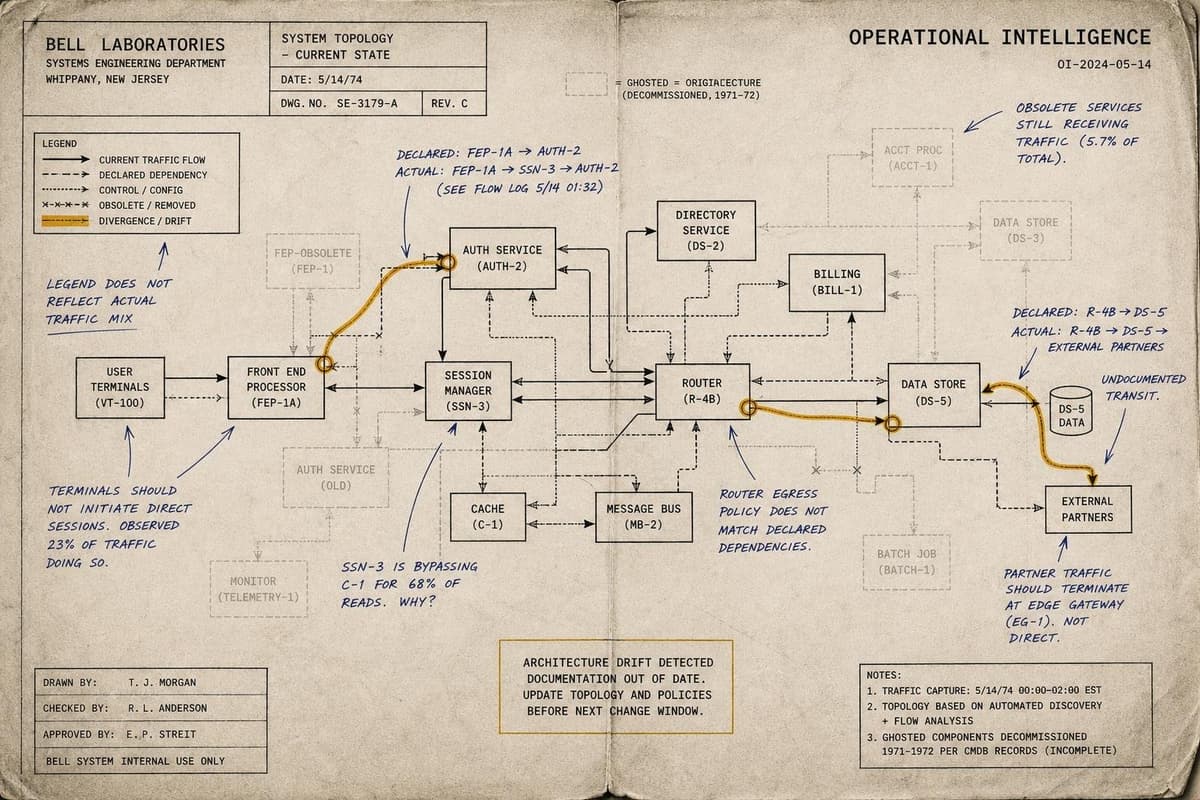
You drew it six months ago. Maybe it was a whiteboard session, maybe a Confluence page with boxes and arrows, maybe just a mental model you've carried since the service launched. I…
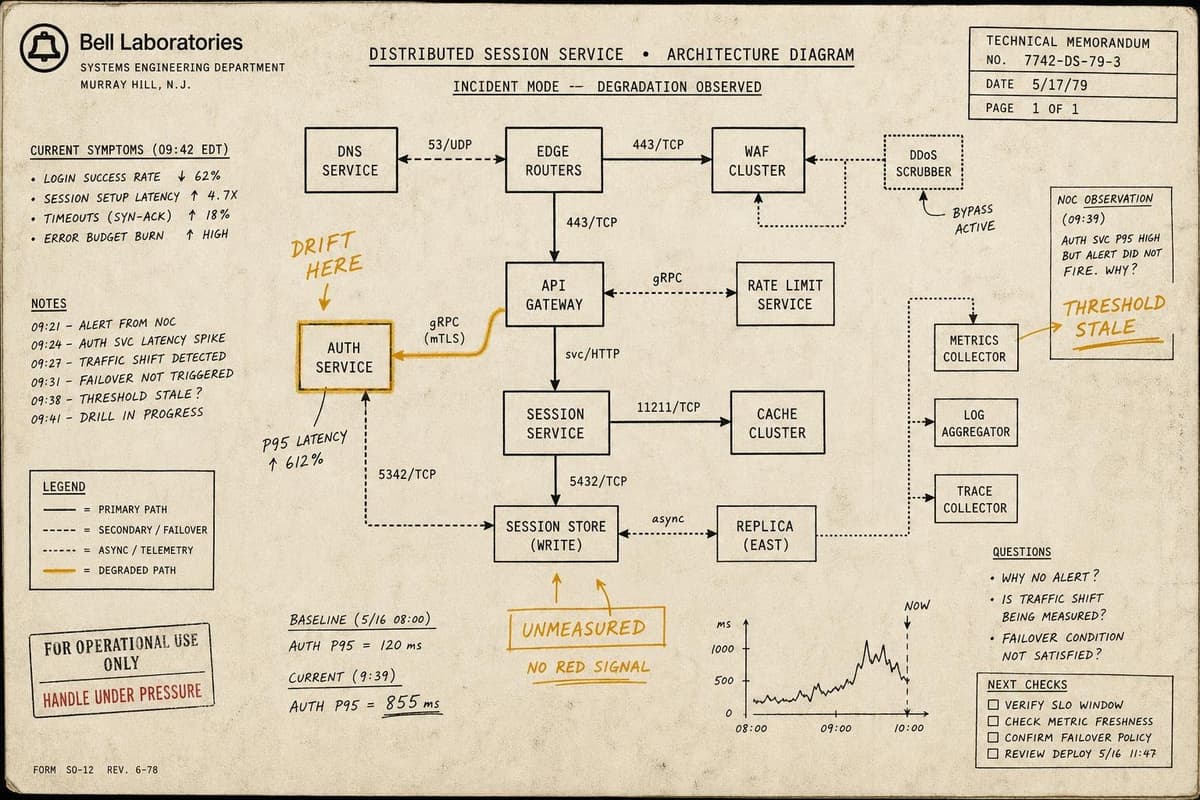
There's a particular kind of confidence that comes from a dashboard that's never been wrong. You built it eighteen months ago, it's been green ever since, and during incidents you…
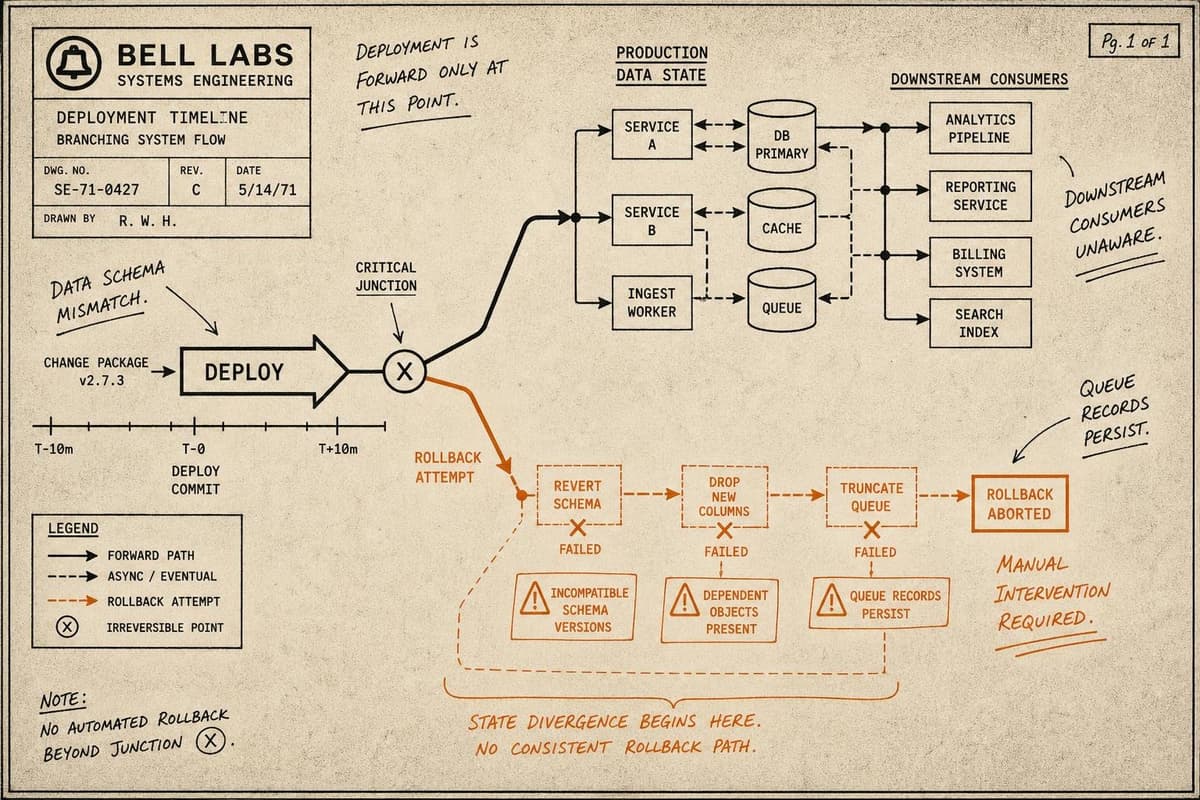
There's a particular kind of confidence that sets in after a deployment goes smoothly a dozen times in a row. The pipeline is green, the metrics look clean, and the rollback proced…
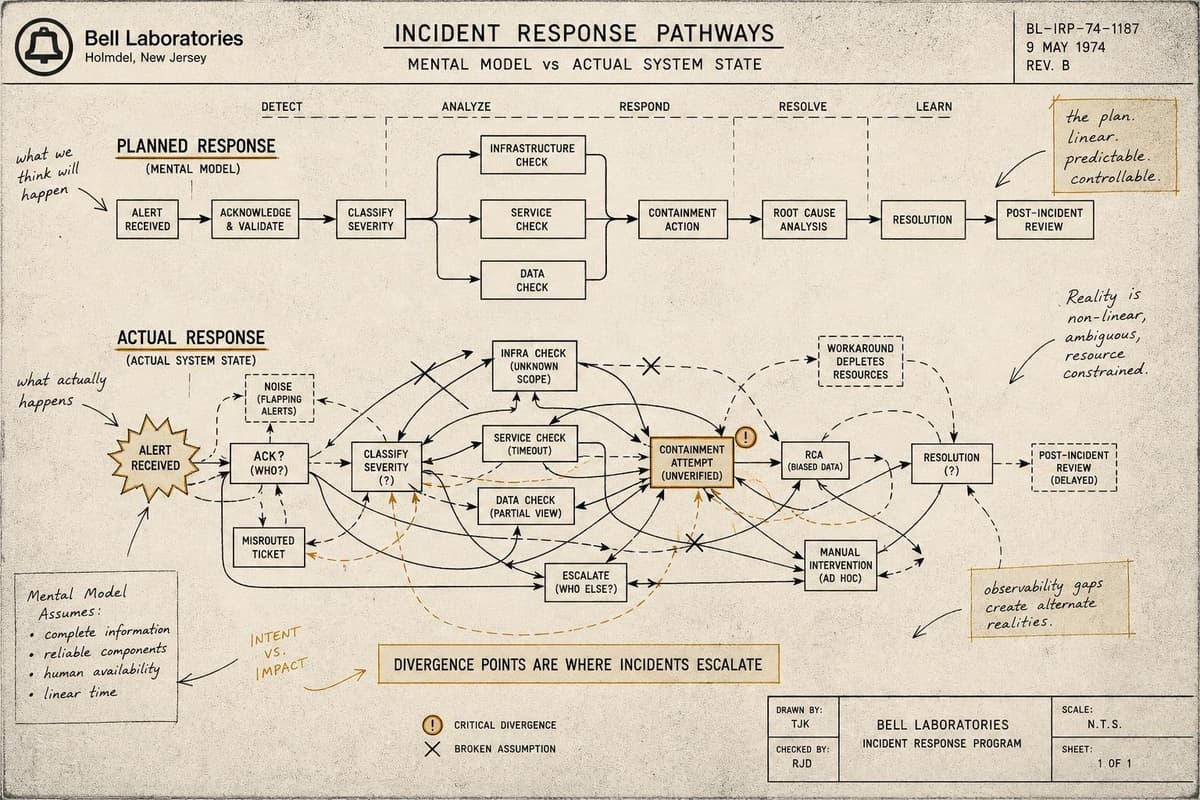
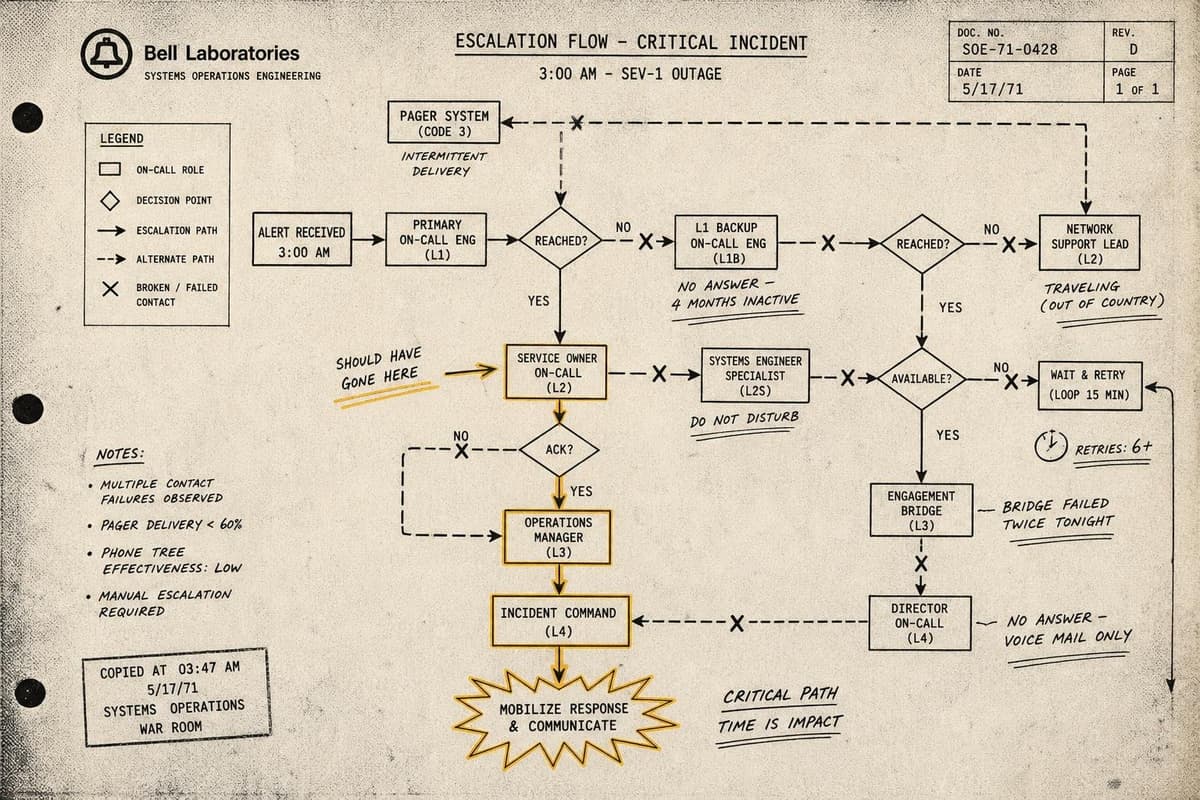
There's a particular kind of confidence that comes from having a good incident response playbook. You've documented the escalation paths. You've defined severity levels. You've run…
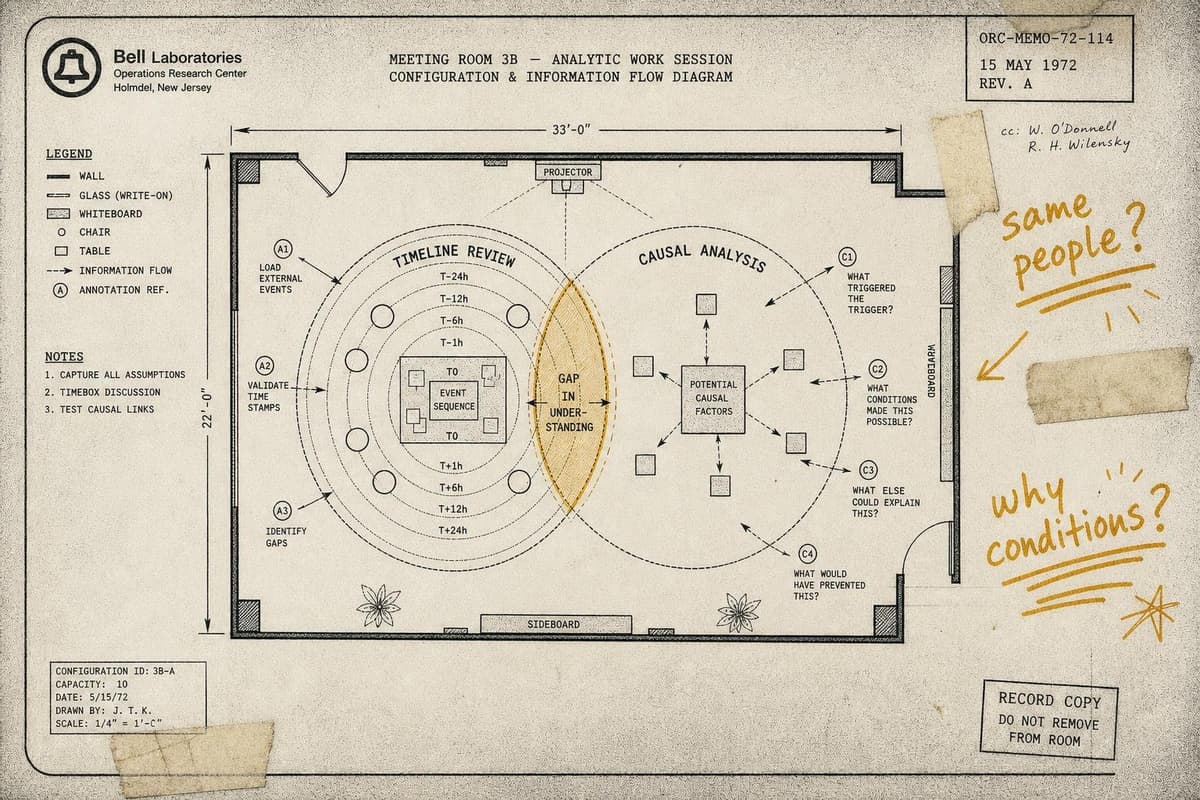
You've been in this meeting. Fifteen people on a call, someone sharing their screen, a timeline of what broke and when. The incident commander walks through the sequence. A few eng…
There's a particular kind of meeting that happens at most engineering organizations, usually sometime in Q1 or after a bad incident. Someone pulls up a blank doc, types "Service Le…
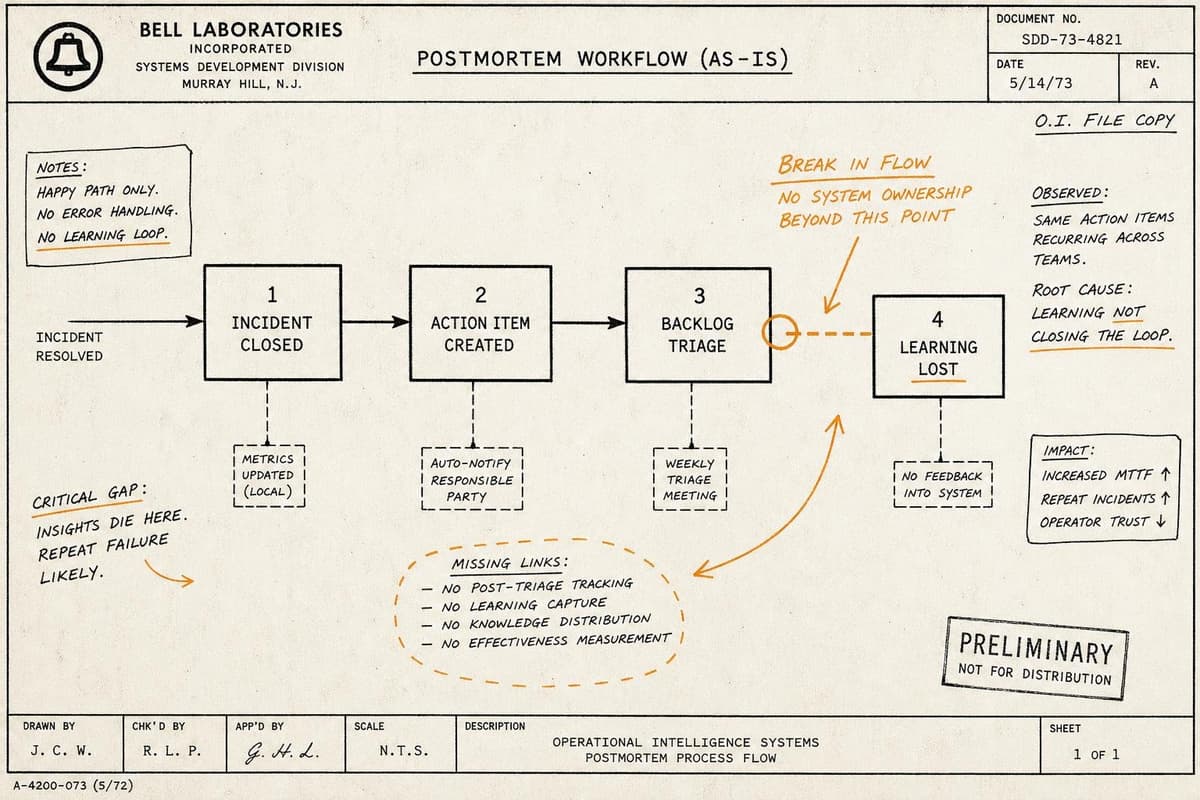
The postmortem is filed. The action items are in Jira. Someone marked the incident resolved at 4:17am and went back to sleep. By Monday morning, the ticket has a due date three spr…
You've tested your rollback procedure. You've run game days. You've validated that your alerting fires within thirty seconds of a threshold breach. What you probably haven't tested…
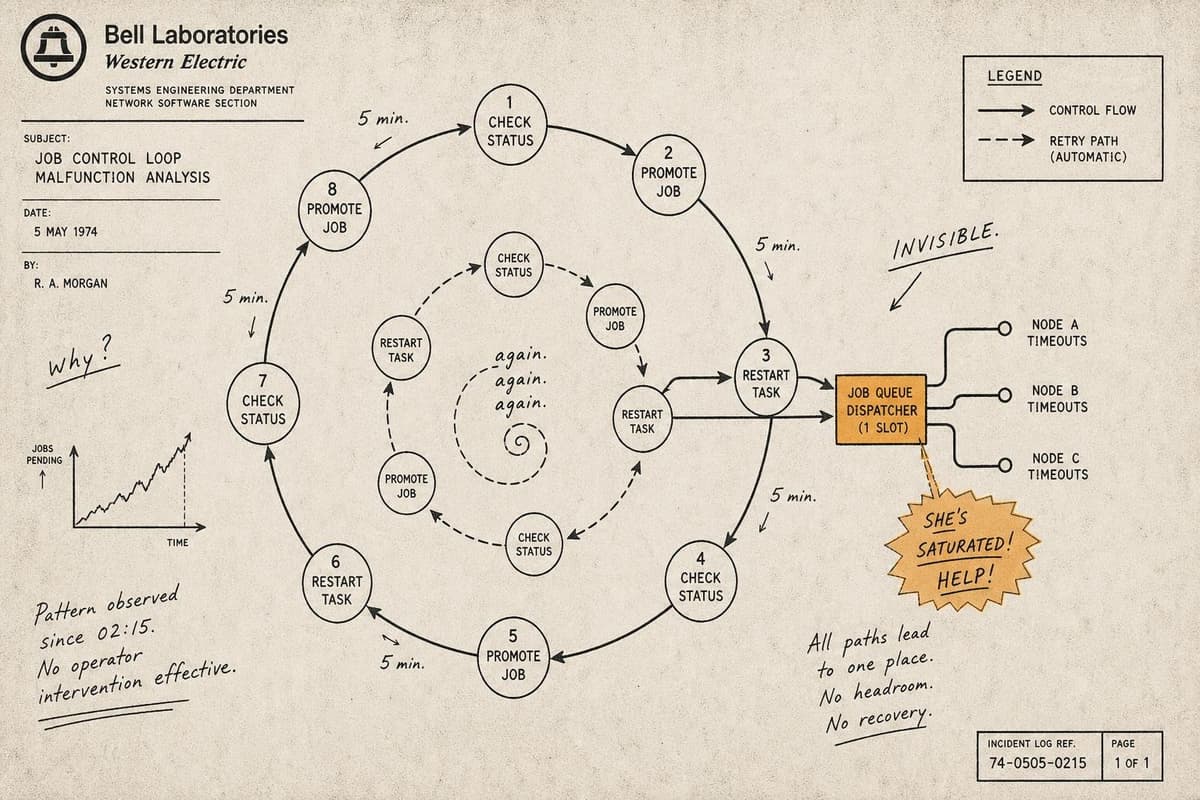
Somewhere on your team right now, someone is doing something for the third time this week that they've done a hundred times before. Restarting a service. Manually promoting a confi…
You schedule the chaos experiment for Tuesday at 2pm. You kill a pod. The system recovers. You write "resilience validated" in the ticket and close it. Three weeks later, a real fa…
The pager fires at 2:47am. Within ninety seconds, three engineers are awake and in the incident channel. Someone starts checking dashboards. Someone else begins restarting services…
There's a particular kind of operational irony that only reveals itself at 2am: the team spent three months building a beautiful observability dashboard, and when the incident actu…
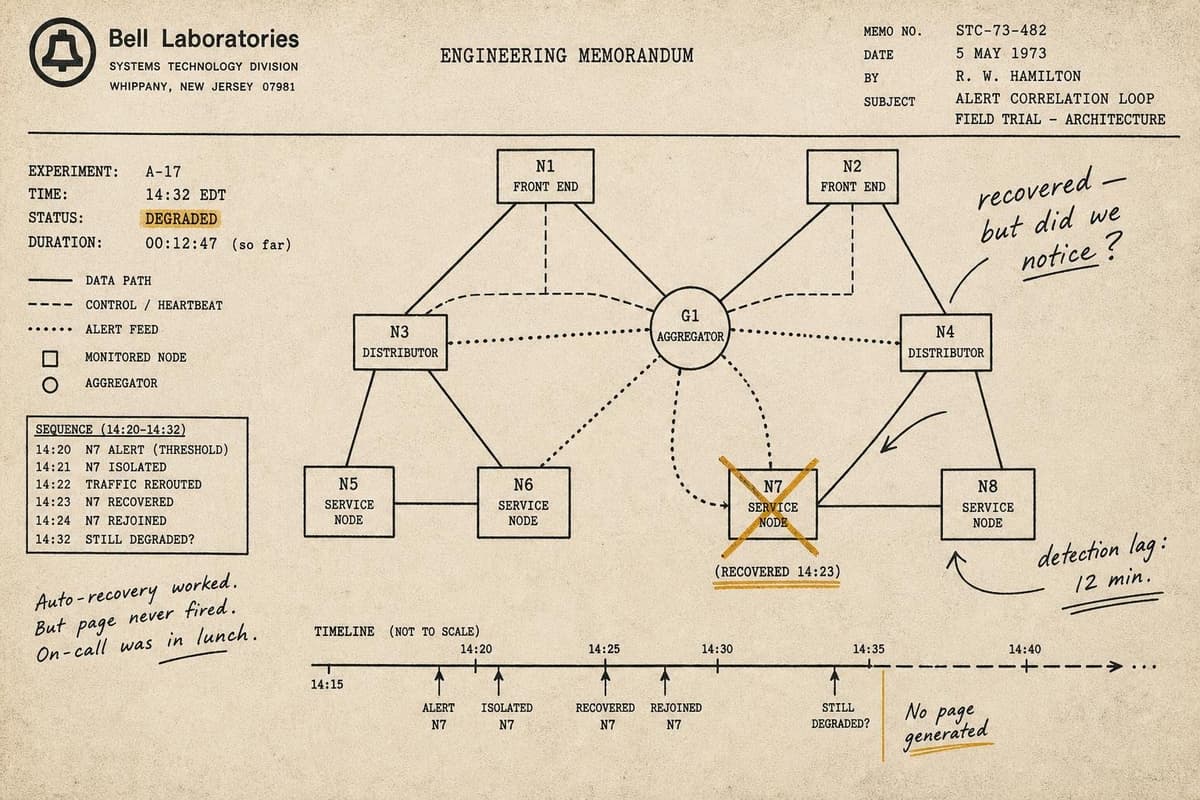
Nobody budgets for the cost of almost-incidents. The production system that degraded for eleven minutes and then recovered on its own. The deployment that caused elevated error rat…