Latest issue
The "Many Analysts" Effect Isn't About Analysts Disagreeing. It's About What Counts as a Fair Test.
10/27/2026
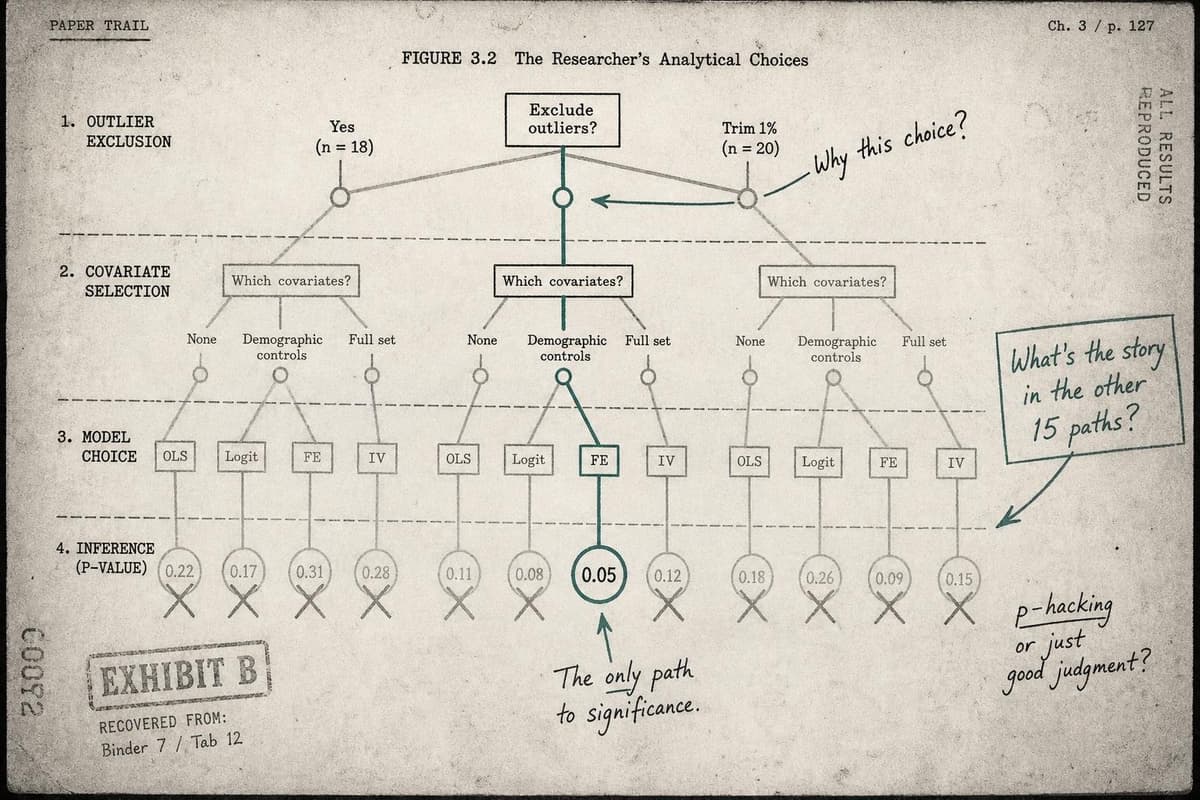
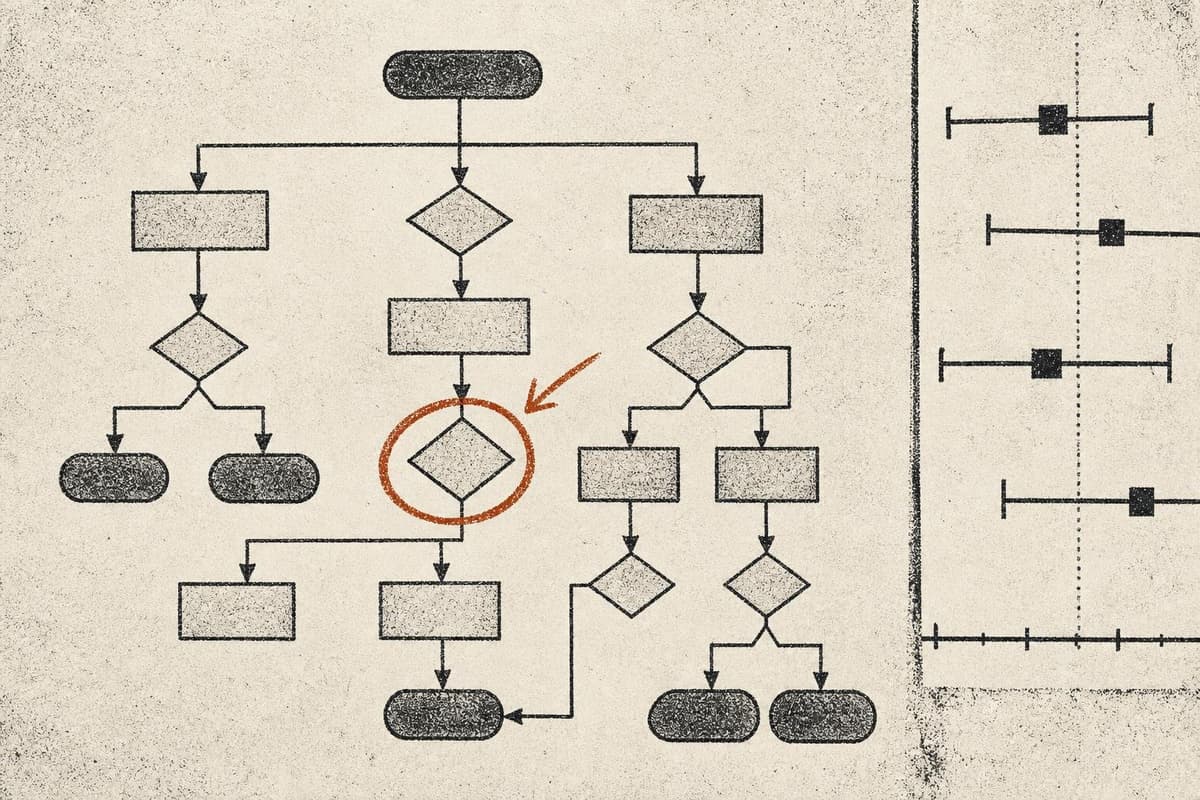
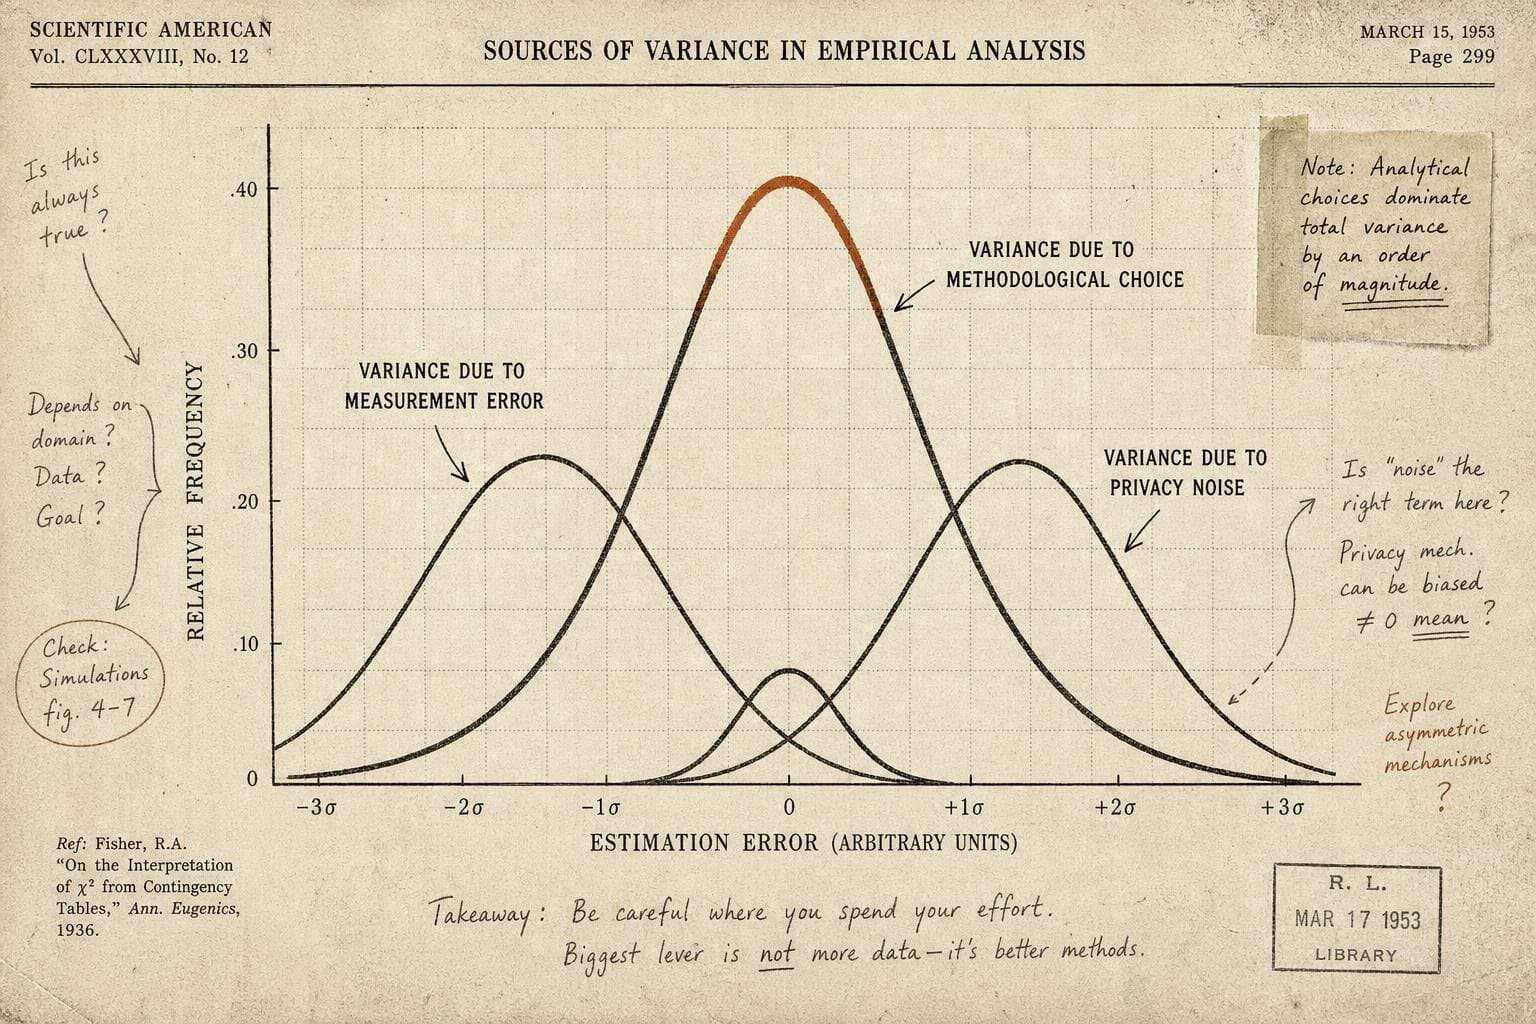
Hand the same dataset to a dozen competent researchers and ask them to test the same hypothesis, and you'll get a dozen different answers — not because anyone cheated, but because "the same analysis" is rarely as well-defined as it sounds. That's the premise behind a wave of rece…
Recent posts
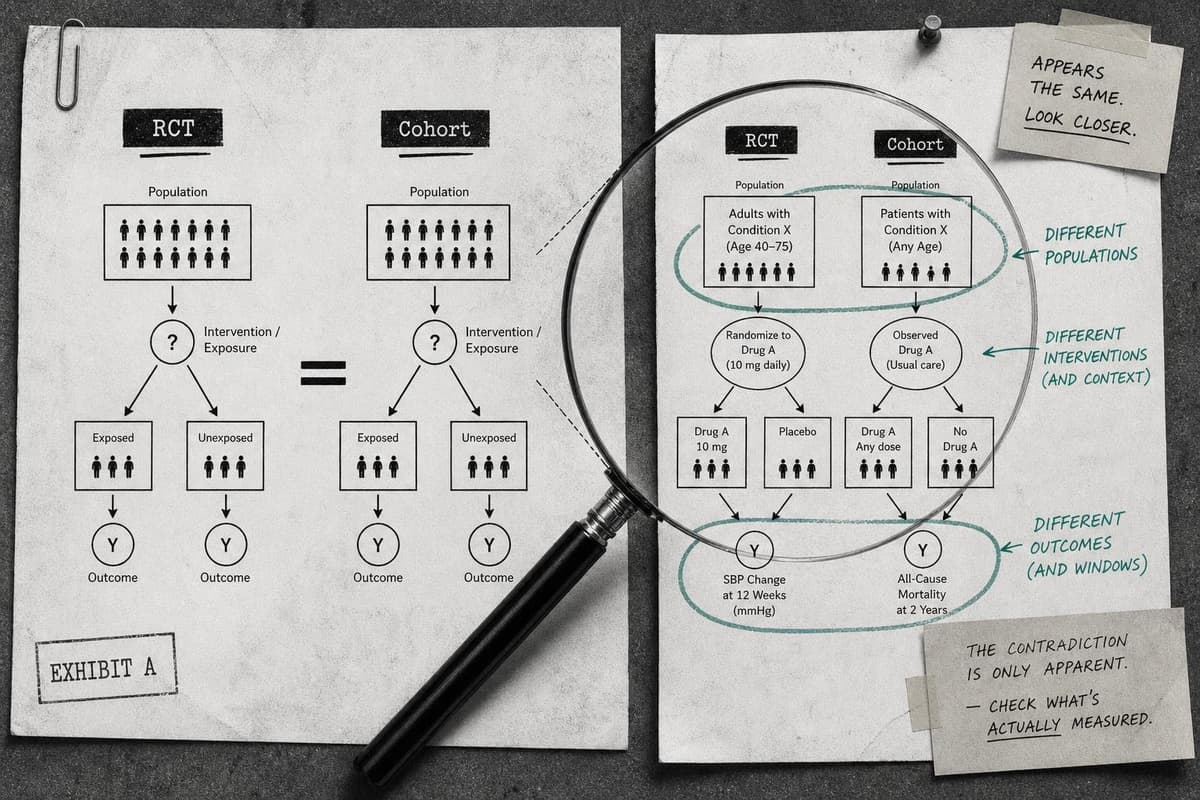
Here's a complaint you've heard a hundred times, maybe from a relative scrolling headlines at Thanksgiving: one study says butter will kill you, the next says seed oils are worse,…
- Papers Are Now Citing Studies That Don't Exist. The Count Is Still Small — and Already Growing Fast.
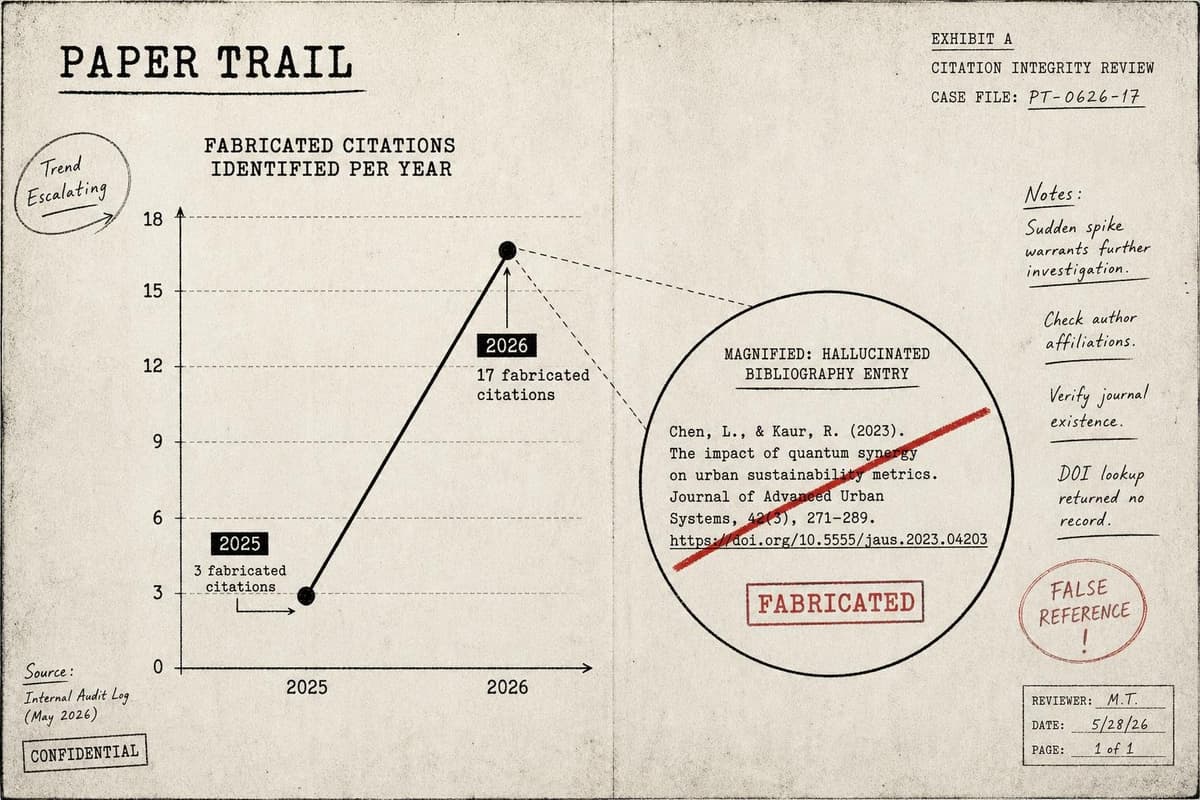
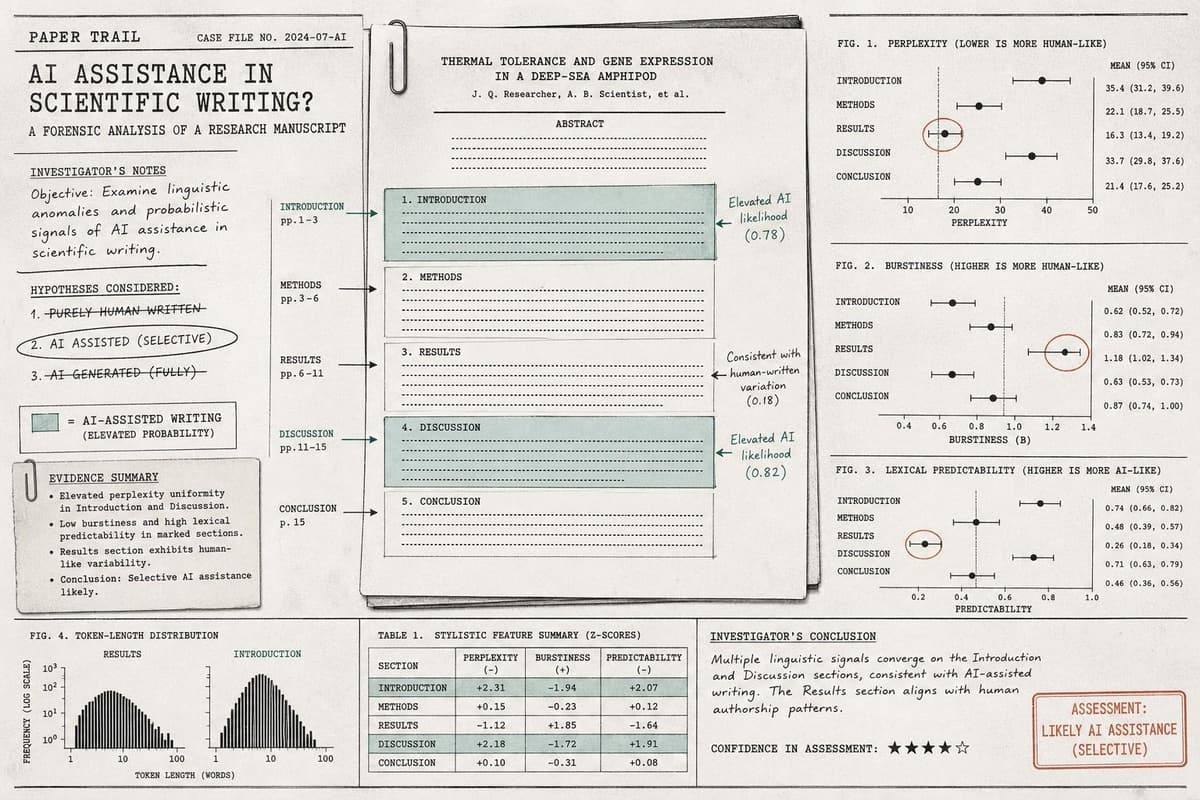
Start with a number: in 2025, three references in papers presented at the ACM's SIGCSE Technical Symposium turned out to be fabrications — citations to studies that don't exist, po…
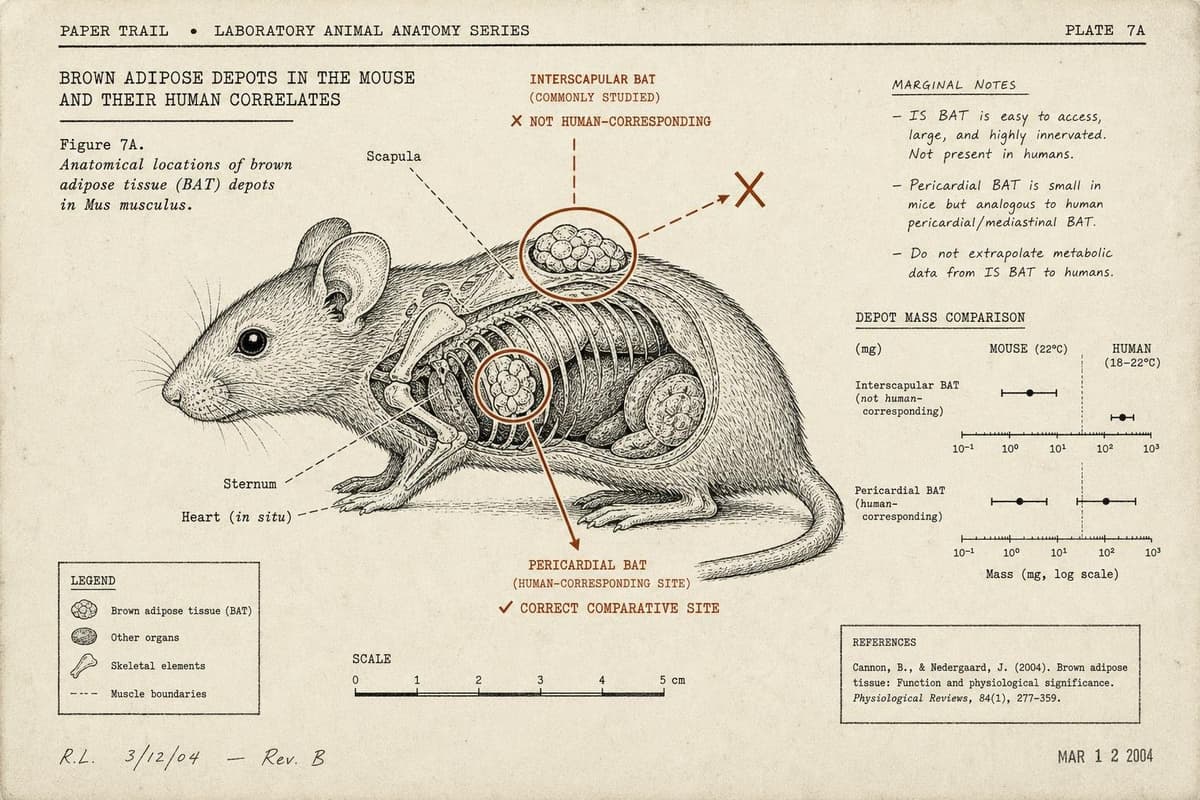
For decades, obesity researchers studying brown adipose tissue — the metabolically active fat that burns energy instead of storing it — have been looking at the wrong body part. A…
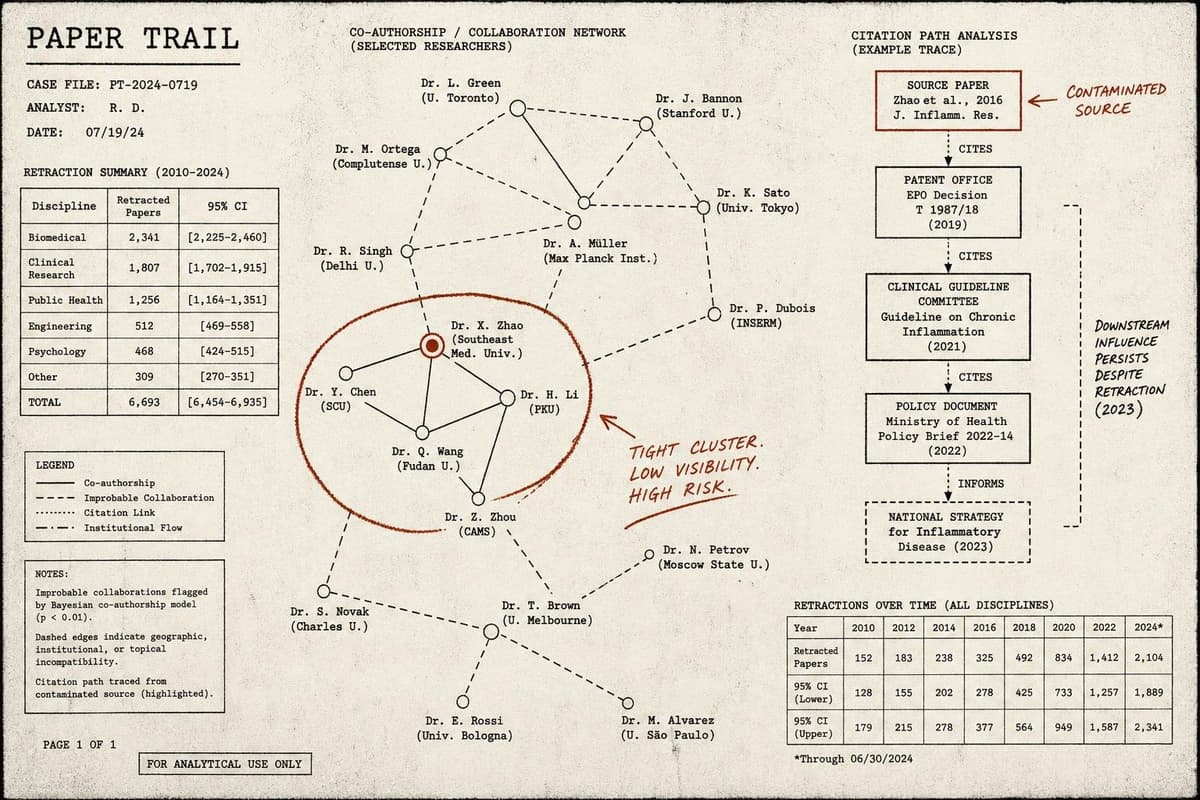
Here's an uncomfortable number: 480 patents, 57 policy documents, and 12 clinical guidelines have cited papers from an authorship-for-sale scheme that isn't even a real research ne…
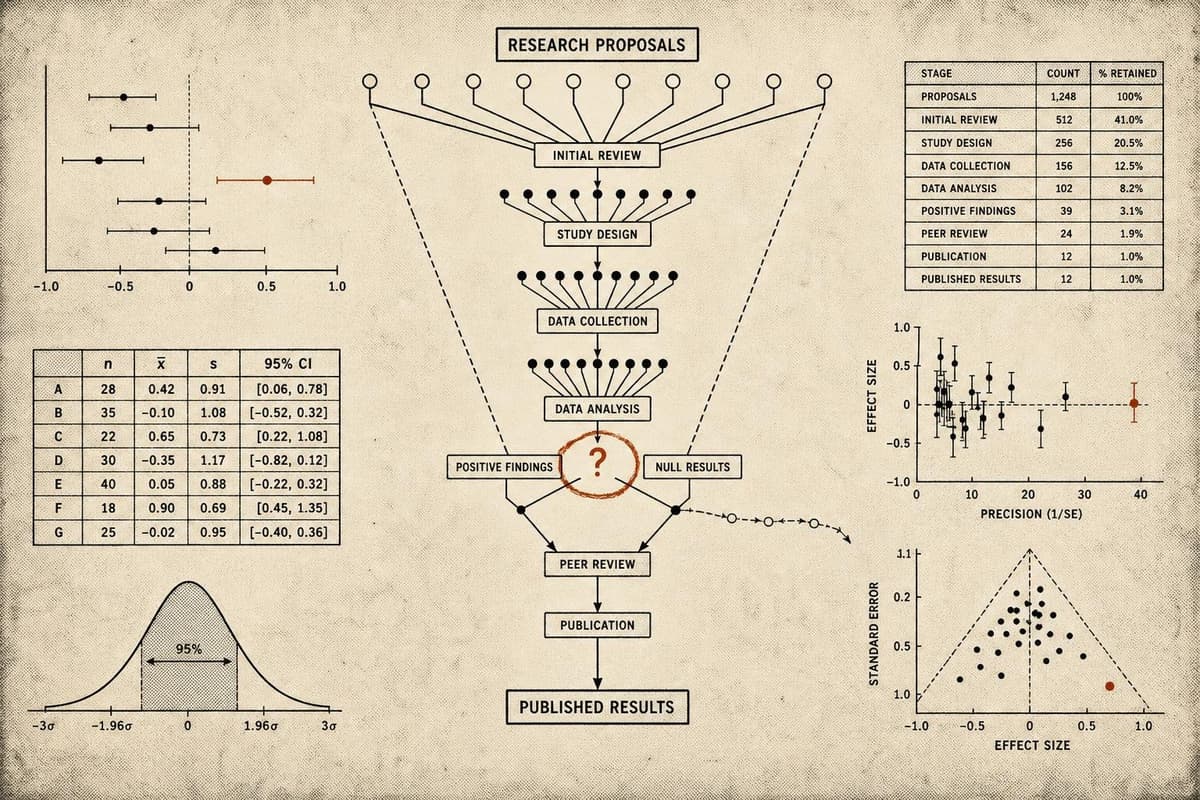
Here's a structural problem that rarely makes headlines: the same system that funds biomedical research also, quietly and systematically, rewards positive results. Not through expl…
Here's a number worth sitting with: in a typical psychology experiment, the odds of getting a statistically significant result by chance — if you test just one hypothesis, once, cl…
Psychology's replication crisis has been well-documented in these pages — the landmark Ariely findings that didn't hold up, the publication bias that buries null results, the struc…
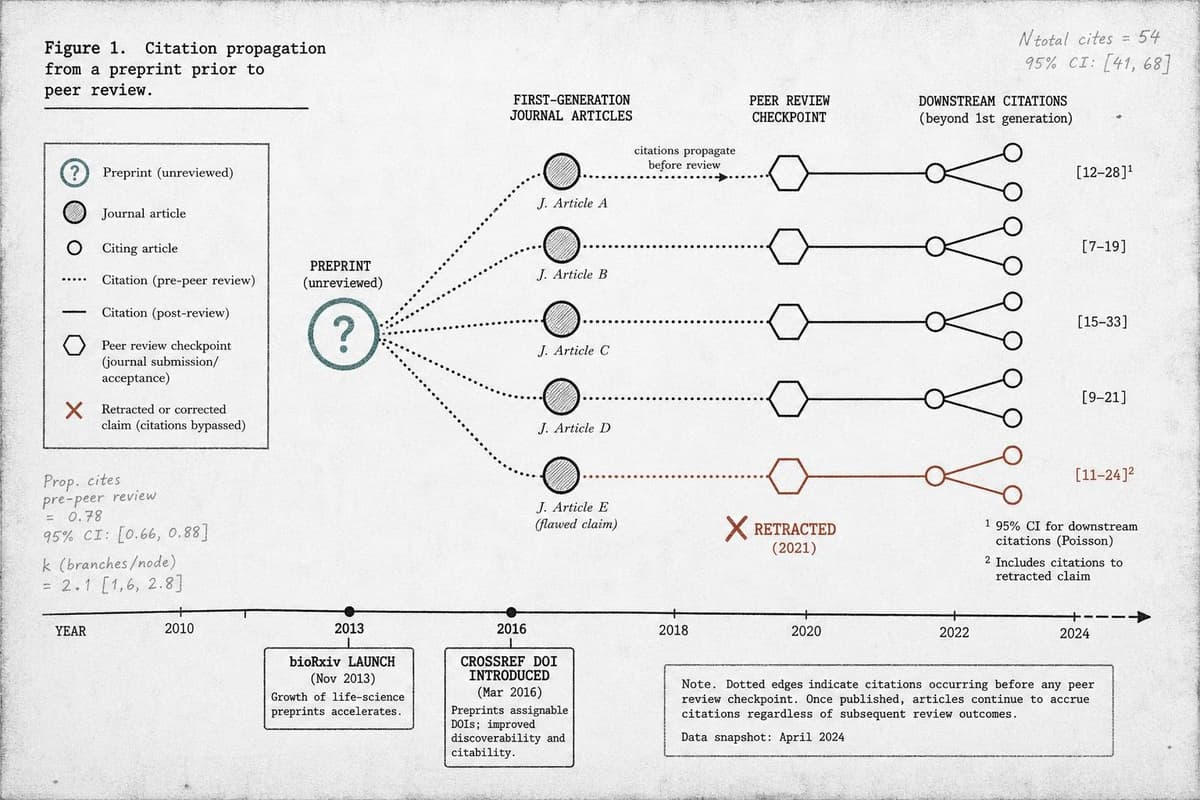
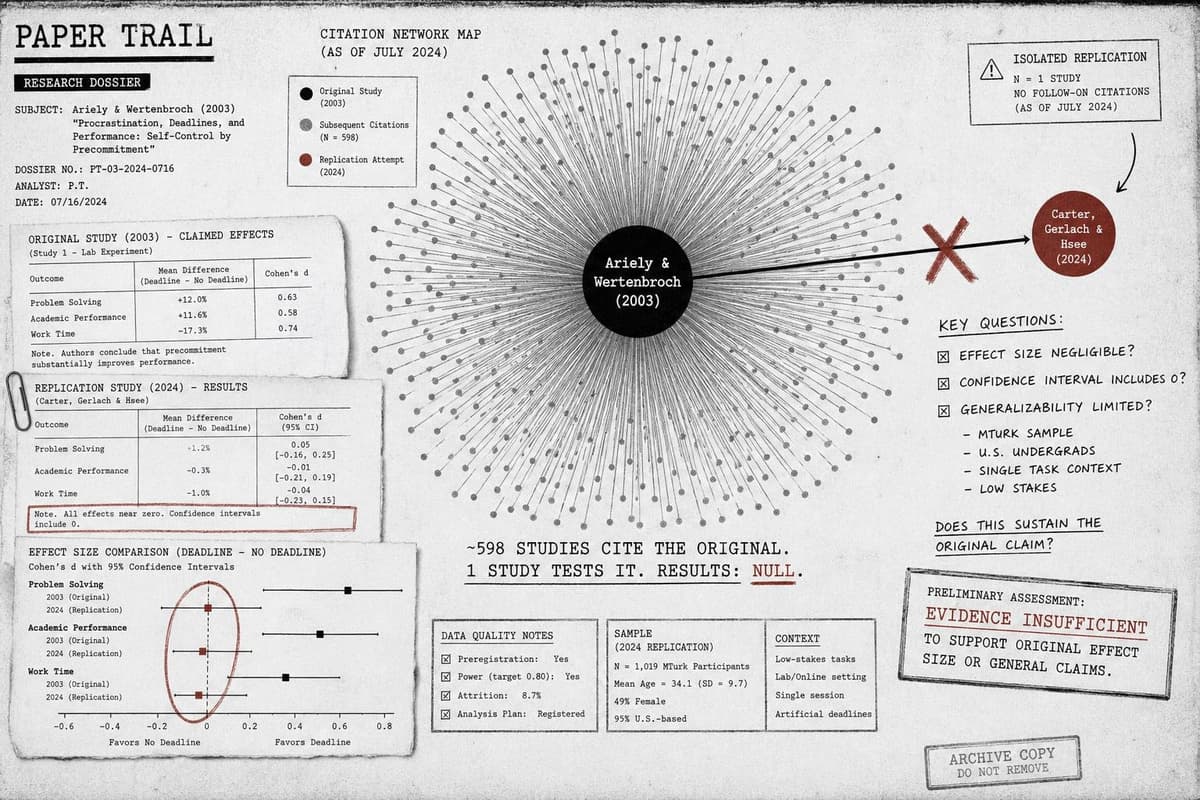
There's a structural assumption baked into how science is supposed to work: you publish a finding, peers review it, journals vet it, and then the broader literature cites it. The c…
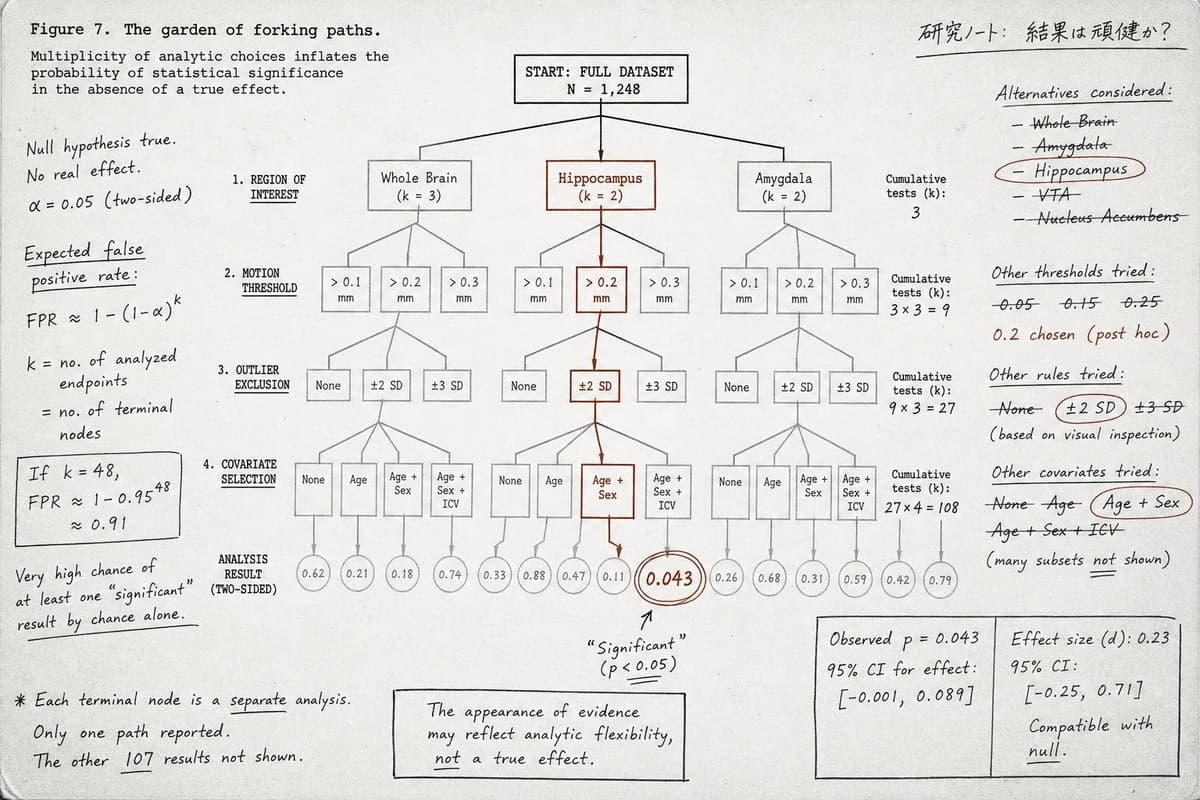
A researcher runs a brain imaging study on 28 participants. The primary analysis doesn't reach significance. So they try a different region of interest. Still nothing. They adjust…
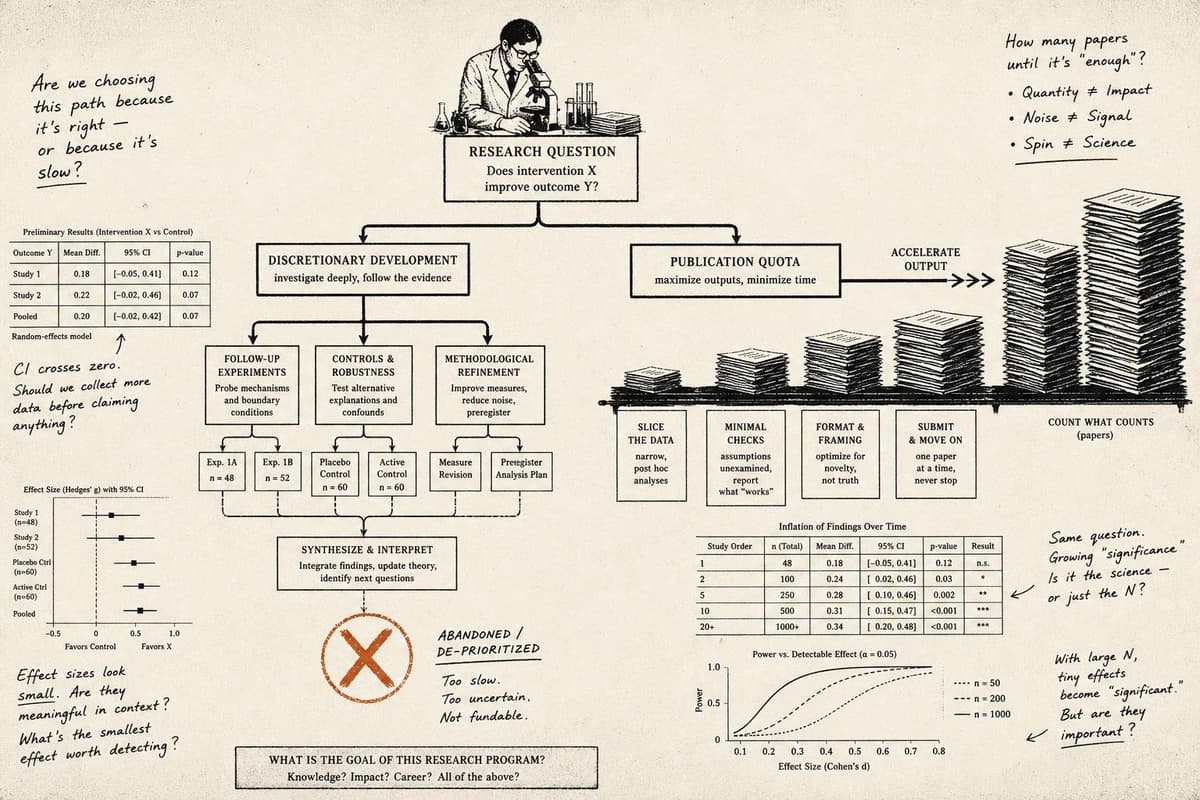
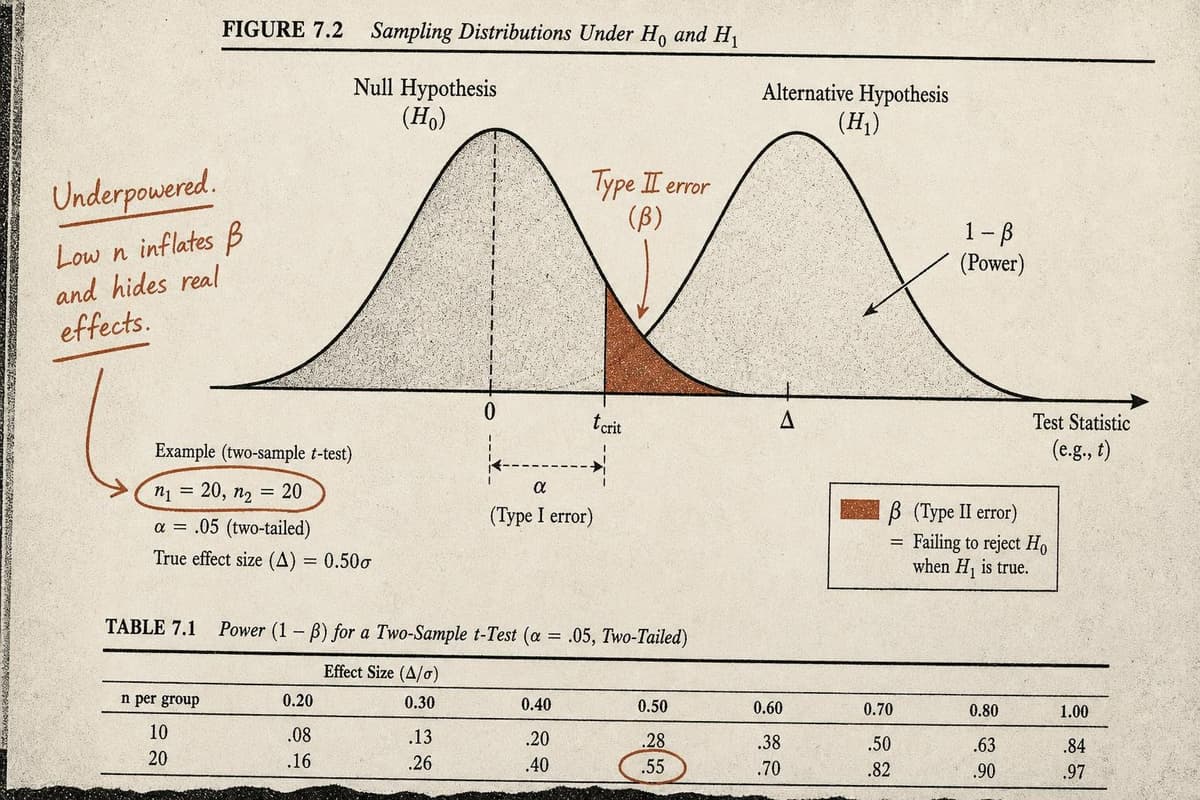
When I wrote about underpowered studies last June, the argument was structural: small samples dominate published research not because scientists are careless, but because the syste…
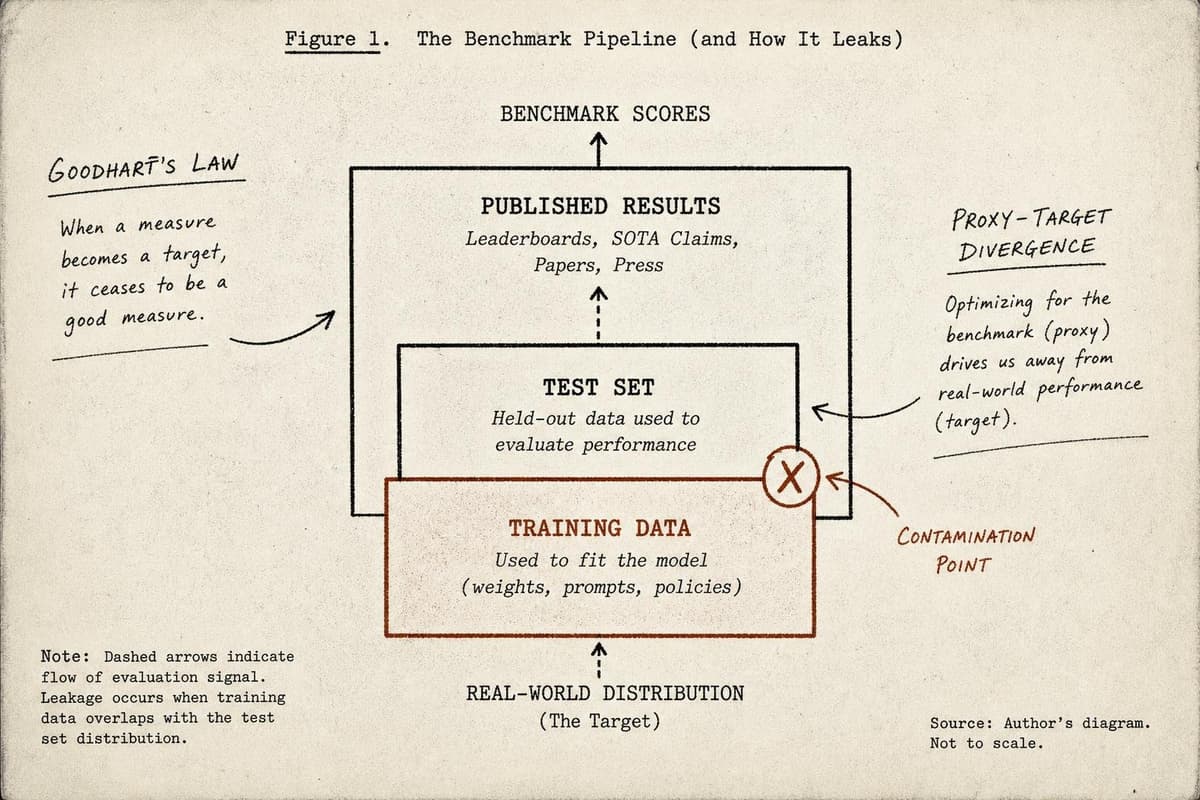
Pick any major AI model release in the past year. Somewhere in the announcement, you'll find a table: rows of benchmark names, columns of model versions, and a satisfying diagonal…
A 2003 paper by Dan Ariely and Klaus Wertenbroch became one of behavioral economics' most-cited findings: that people perform better when they can precommit to evenly spaced deadli…
Here's a number worth sitting with: in a survey of principal investigators running randomized controlled trials in sub-Saharan Africa, roughly 14% of those who failed to publish ci…
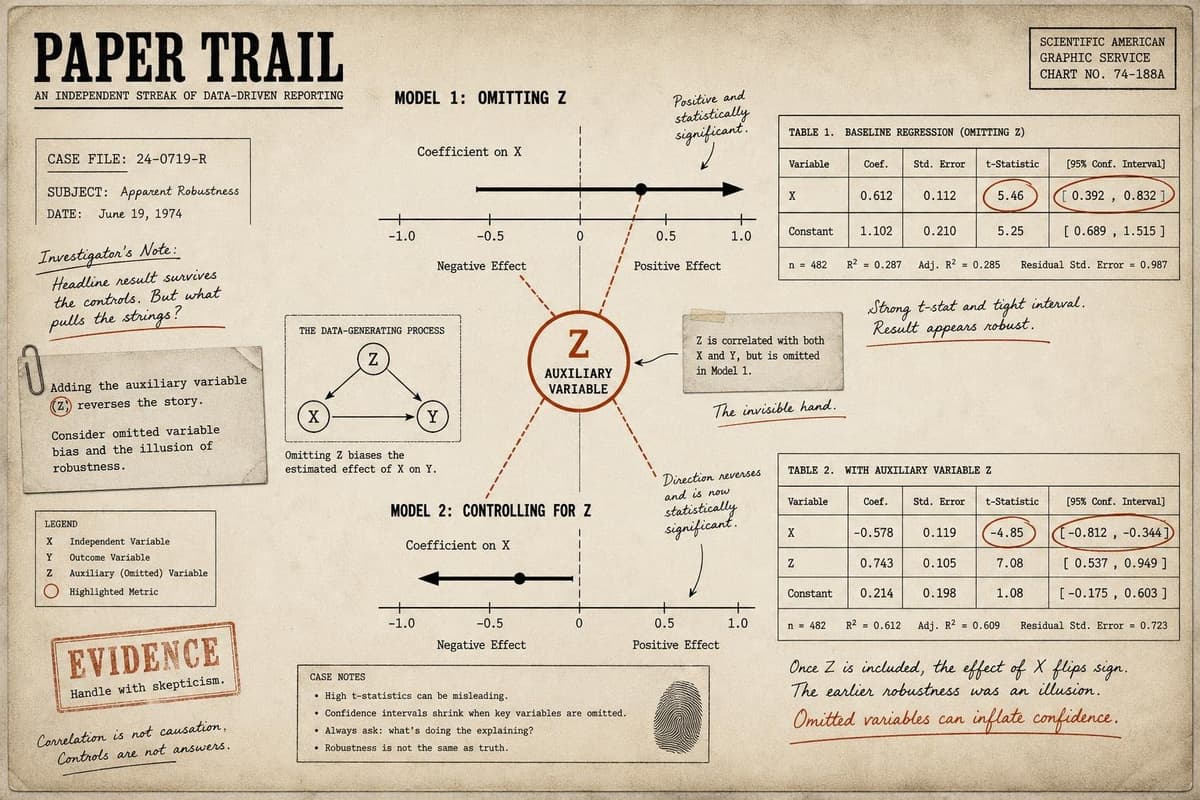
There's a version of p-hacking that everyone in research methods knows about: run your analysis twenty different ways, report the one that clears p < 0.05, and call it a day. It's…
Here's a scenario that should unsettle you. A research team runs a study on 40 participants, finds a striking effect, publishes in a respectable journal, and watches the press rele…
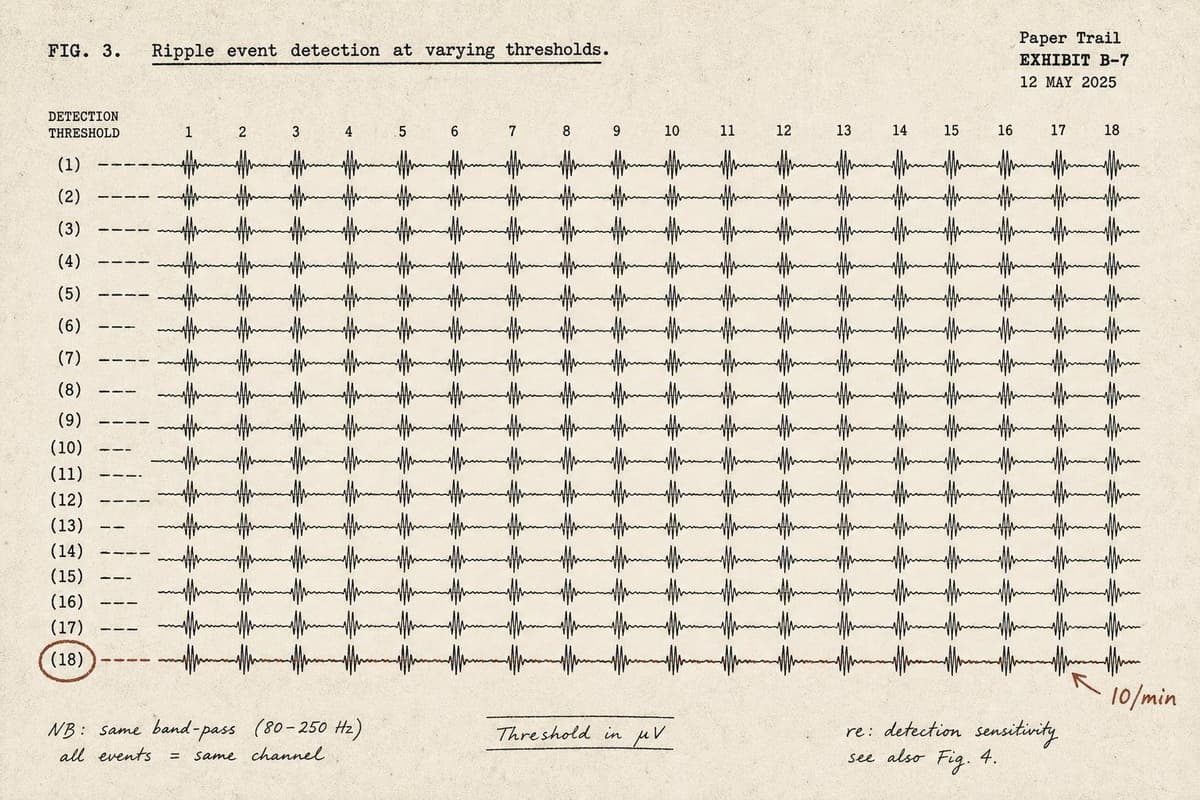
Last spring, eighteen teams of neuroscientists sat down with identical brain recordings and tried to answer the same question: which region had the highest density of hippocampal s…
A paper published in the latest issue of Methods in Ecology and Evolution proposes something called "adaptive preregistration" — a framework that, its authors argue, handles the me…
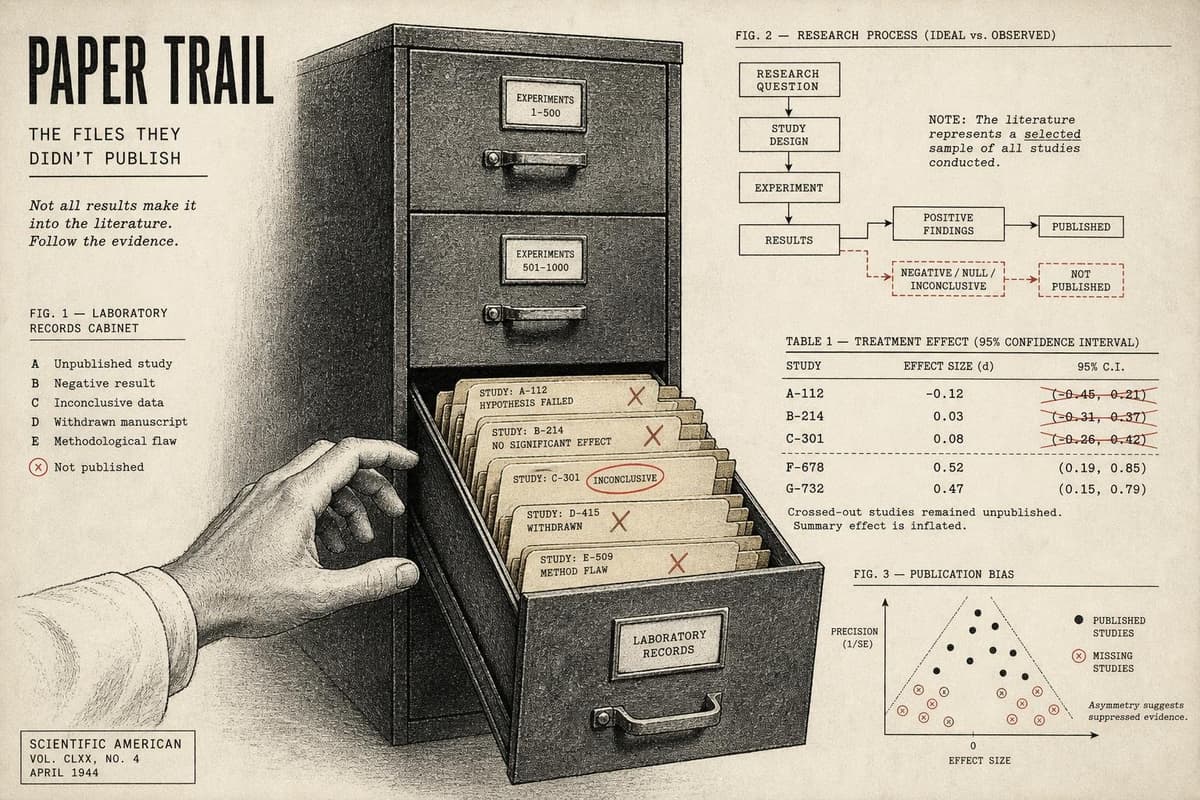
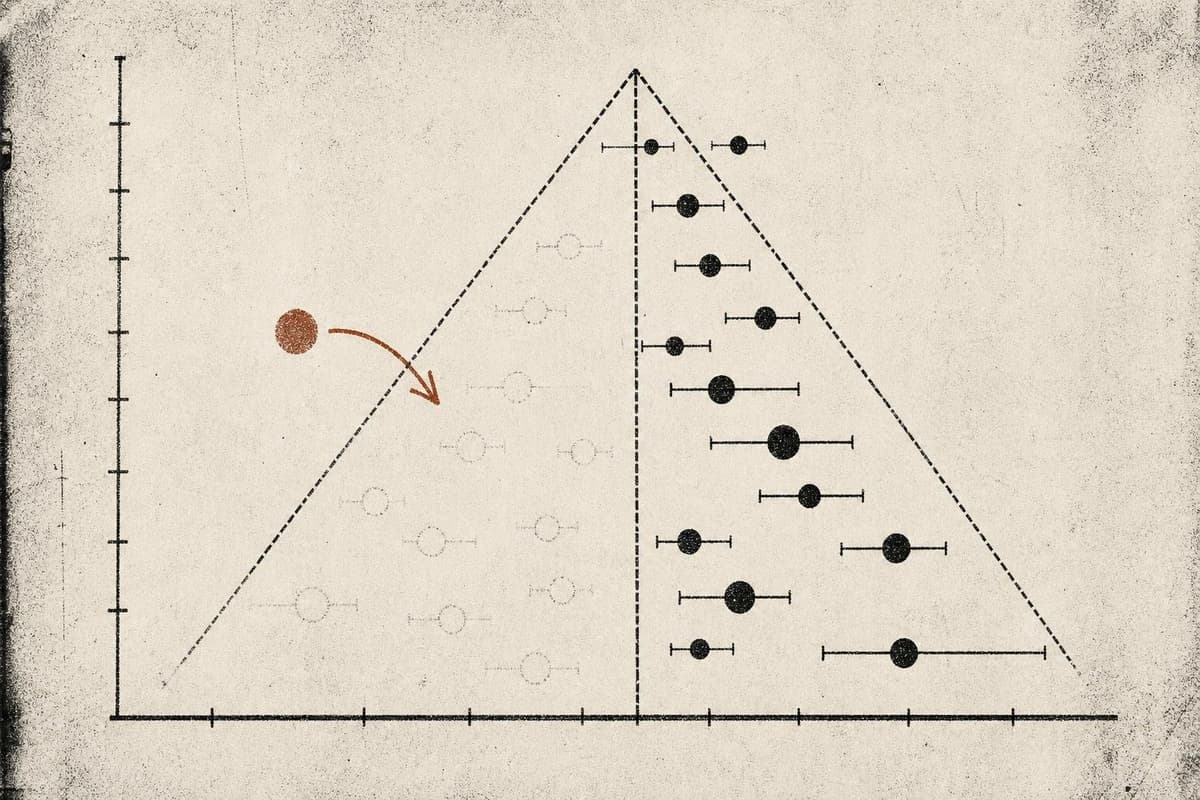
Imagine a drug that gets tested in twelve independent clinical trials. Three find a statistically significant benefit. Nine find nothing. If all twelve get published, the picture i…
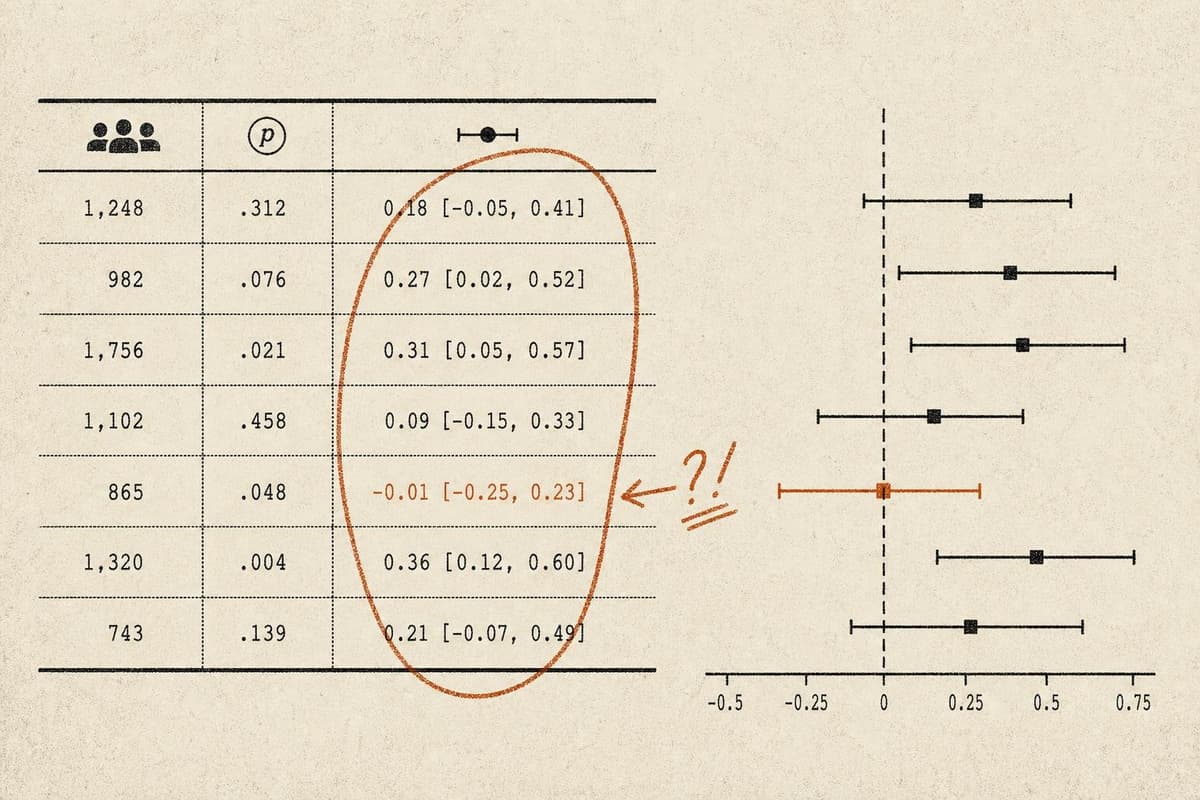
A clinical trial enrolls a thousand patients. The new antidepressant beats placebo. The p-value is 0.03 — statistically significant, publishable, press-releasable. The drug reduces…