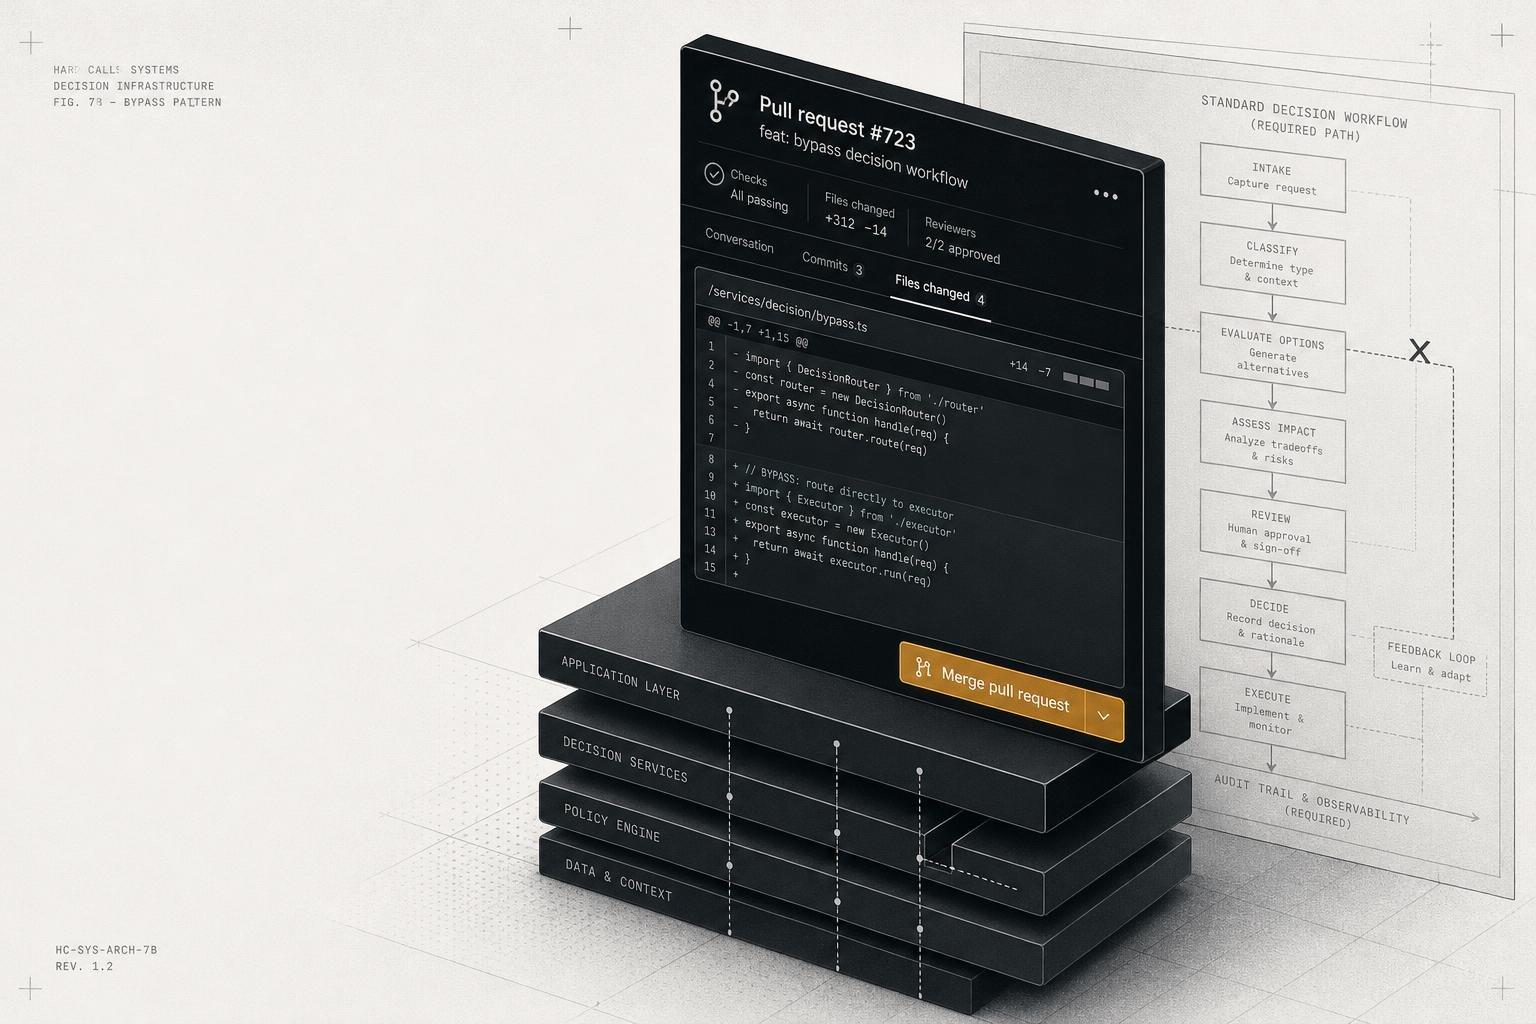

A team at a mid-sized company skipped its usual technical design review, let a PRD go straight into a few coding agents, and watched the pull requests come back clean, tested, and wrong. Not broken-wrong — the assumptions baked into the implementation reflected patterns from individual codebases instead of the org's actual architecture, and the code skipped precautions the team normally took on critical paths. Nobody caught it until reviewers flagged it in a group chat, after the fact, when the only artifact left to argue over was finished code (LeadDev).
That's the scenario I'd point to if you're trying to figure out whether your team needs a formal RFC process. Not "we hit fifteen engineers" or "we added a second office." The actual trigger is a recurring, specific failure mode — and right now, the most common one is that implementation has gotten fast enough to outrun judgment.
Headcount Isn't the Trigger. A Named, Recurring Failure Is.
The instinct to add process at a size threshold is understandable and usually wrong. Ka Lun Chan's framing is the cleanest version of this I've seen: process earns its keep when it solves a specific, recurring problem whose cost exceeds the process itself — unclear ownership, missed handoffs, unpredictable delivery, repeated quality failures, or an external requirement like a security clause in a contract. Headcount makes those problems more likely but isn't itself the cause, and "we're bigger now" doesn't tell you which failure you're actually dealing with, which means it can't tell you which process fixes it (Ka Lun Chan).
That distinction matters because the common failure mode for RFCs right now isn't two teams quietly duplicating effort — it's a product requirements document turning directly into a pull request with nobody in between asking whether the approach is right. The LeadDev piece is explicit that tools like GitHub's Spec Kit can take requirements, inspect the repo, plan changes, and ship working PRs without anyone ever challenging the design — code that delivers the requested behavior isn't the same as code that's the right technical solution to the problem (LeadDev).
If that's your actual failure — design decisions getting made implicitly, inside a coding agent's context window, instead of explicitly in front of the people who'd catch a bad assumption — then the fix is a review gate before implementation, not a meeting culture overhaul.
The Document Has to Force a Decision, Not Invite a Debate
Here's where most RFC processes die even after teams correctly decide they need one: the template produces a document that generates forty comments and a meeting that ends in "let's take this offline," instead of a decision (DEV Community). The pattern that actually works is narrower than most teams build. Named non-goals, so "what about X" has a one-line answer instead of a derailing conversation. At least two real options in a comparison table, because a doc with a single option is an announcement and reviewers will invent the alternatives for you anyway. A stated winner and why it wins for this specific context, not an abstract best practice (DEV Community).
Not every decision needs that weight. One practitioner building a written-decisions culture at StrangeBee settled on calling theirs RFDs instead of RFCs partly because "comments" implies reviewing someone else's finished idea, while "discussion" invites people in before the shape is set — and the lighter version, an Architecture Decision Record, covers smaller calls in half a page (0xDC.me). The point of both formats is the same: a future engineer, or a future version of you, can find out why a decision was made instead of reverse-engineering it from the code.
What I'd Actually Check Before Standing One Up
Before you write a template, I'd ask what's actually failing. Is it that nobody agrees who owns a decision until it's already shipped? Is it that your fastest path from idea to PR has stopped passing through any human who'd push back? Those are different diseases with different cures, and a generic "we need an RFC process now" skips the diagnosis.
It's also worth asking whether the real constraint is process at all. One useful reframe from an engineering leader at Stripe: adding people and adding process both buy you complexity as often as they buy you capacity, and the more durable fix is often concentrating ownership in smaller pods rather than layering review gates on top of a structure that's already unclear about who decides what (CIO). A formal review process can paper over an ownership problem for a while. It won't fix one.
The signal to watch for isn't team size. It's how many times in the last quarter a decision got made by default — inside a PR, inside a PRD, inside an agent's output — instead of in front of the person who'd have said no.


