


I wrote about retrieval quality back in April (/p/your-rag-pipelines-retrieval-layer-is-lying-to-you), and the core problem hasn't changed: a RAG pipeline can look healthy on every dashboard you have and still hand a customer a wrong answer with full confidence. What's changed is how many teams are now publishing the metrics they wish they'd tracked from day one — and it's worth revisiting because "accuracy" as a single number is still the wrong lens.
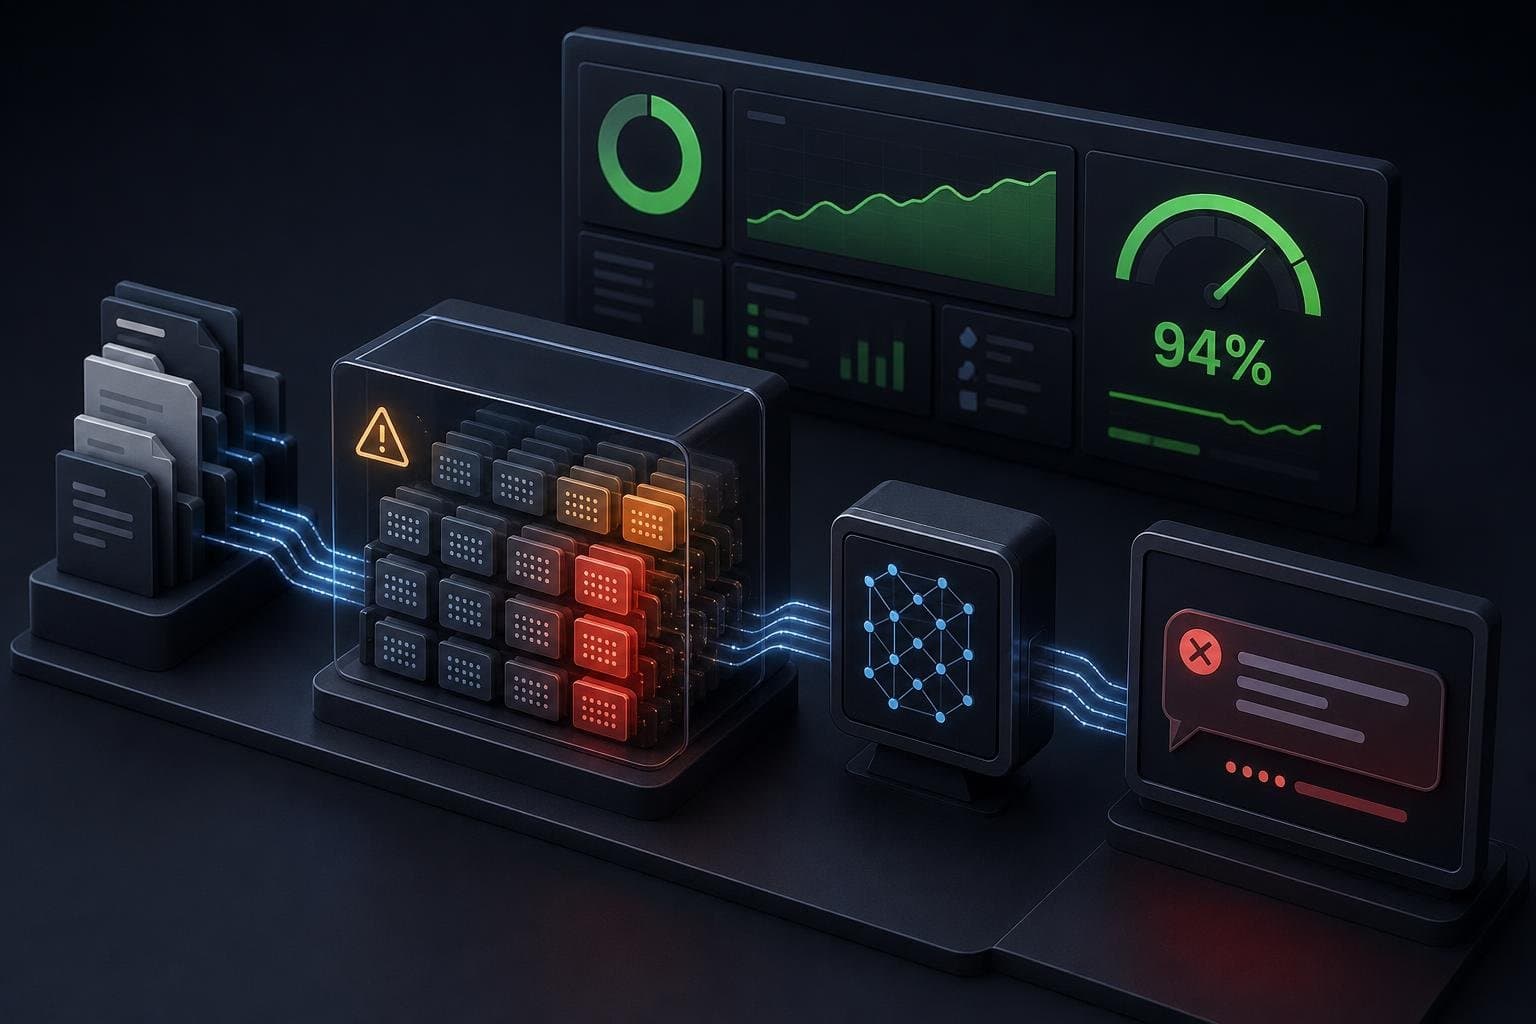
Here's the scenario that keeps showing up in practitioner write-ups: a refund assistant gets asked whether an opened blender can be returned after 40 days. It answers in 400 milliseconds, returns a valid HTTP 200, and the JSON parses cleanly against the schema — {"eligible": true, "reason": "Opened items can be returned within 60 days"}. Every infrastructure signal is green. The answer is wrong, because the policy changed to a 30-day window last quarter and the stale chunk never got purged from the index, as Formation's engineering blog lays out. Latency, error rate, and schema validation don't catch this. Nothing in a standard ops dashboard is built to.
Precision and recall are necessary. They are not sufficient.
The reflex fix is to bolt on retrieval metrics — precision@k, recall@k, mean reciprocal rank, nDCG — and call it done. These matter. A DEV Community writeup on RAG evaluation walks through implementations of each: precision@k tells you what fraction of your top-k retrieved chunks are actually relevant, recall@k tells you what fraction of the relevant universe you managed to surface, MRR tells you how far down the list the first useful chunk sits. If you're not computing at least one of these against a labeled set, you're flying blind on the retrieval step specifically.
But here's the trap: all four of those metrics assume you already have ground-truth relevance labels, and they only tell you whether retrieval found the right documents — not whether the system then did anything correct with them. A retriever can score well on recall@5 and still hand the model a chunk that's technically on-topic but superseded, contradictory, or missing the one sentence that changes the answer. That's exactly the blender case. The retrieval metric passes. The business outcome fails.
Groundedness is the metric that catches what retrieval metrics can't
This is where groundedness earns its keep — scoring whether the model's claims are actually supported by the context it was given, rather than scoring whether the context itself was topically relevant. Formation's framing treats groundedness as the meeting point between two things most teams keep separate: traces that record what each pipeline stage did, and evaluations that judge what the output says. A trace tells you the request took 1.4 seconds and made three tool calls. It doesn't tell you the answer was ungrounded. You need both running simultaneously, and most teams I've seen have only built the first half.
Practically, that means instrumenting the retrieval stage itself, not just the model call. Last9's observability guide recommends giving every stage of the pipeline — query rewrite, embed, retrieve, rerank, generate — its own span, recording top-k count, top retrieval score, and result count as attributes. The payoff is being able to see retrieval scores drifting over time even when p99 latency and error rate stay flat. A vector index that starts returning low-confidence matches for a growing share of queries is a leading indicator of exactly the failure mode above, and it shows up weeks before users start complaining.
The metric only matters if someone's watching for the drift
None of this is abstract. Fiddler's eval writeup makes the point that evaluation isn't a pre-launch gate — it's a continuous loop that has to keep running once the system is live, because the same request can pass today and fail next week if the underlying index, prompt, or model shifts. That's the part teams skip. They build the eval harness, run it once before shipping, and then treat the dashboard's green status as permission to stop looking. The blender bot didn't break because nobody built evals. It broke because nobody was sampling live traffic for groundedness after the policy document changed.
If you're running a RAG system right now, the test isn't whether your retrieval metrics look good in a notebook. It's whether you have any signal that fires when a stale chunk starts winning the top-k slot, before a customer finds out the hard way. Precision@k and recall@k tell you if retrieval is doing its job on a fixed test set. Groundedness, measured continuously against live traffic, tells you if it's still doing that job six weeks after your last document refresh. Build for the second question — the first one you'll have already answered in staging.